Researchers at SAP Labs have proposed a way to create synthetic enterprise data by making an AI agent interact with simulated business systems instead of asking a model to generate database rows directly. The approach, called Synthesis Through Simulation, or STS, is described in an arXiv preprint submitted September 24. Its central claim is that data created through policy-enforcing application programming interfaces can remain structurally valid without exposing the underlying database schema or production records.
The work targets a persistent obstacle for enterprise agents. Training and evaluating systems that book flights, update employee records or operate other business workflows requires populated environments with realistic relationships between records. Real databases may contain personal or commercially sensitive information, while their schemas can reveal proprietary system designs. Conventional synthetic-data tools can imitate statistical patterns, but the paper argues that they often miss business rules that depend on the live state of several related records.
STS moves enforcement into the simulated environment. Every attempted write passes through an API that checks the relevant business policies before changing the database. A leave request, for example, can be rejected if it exceeds an employee's available balance. Because rejected operations leave the database unchanged, the authors define structural validity as guaranteed by construction, provided the simulated API actually encodes all relevant rules. The model can then concentrate on producing realistic distributions rather than learning every constraint itself.
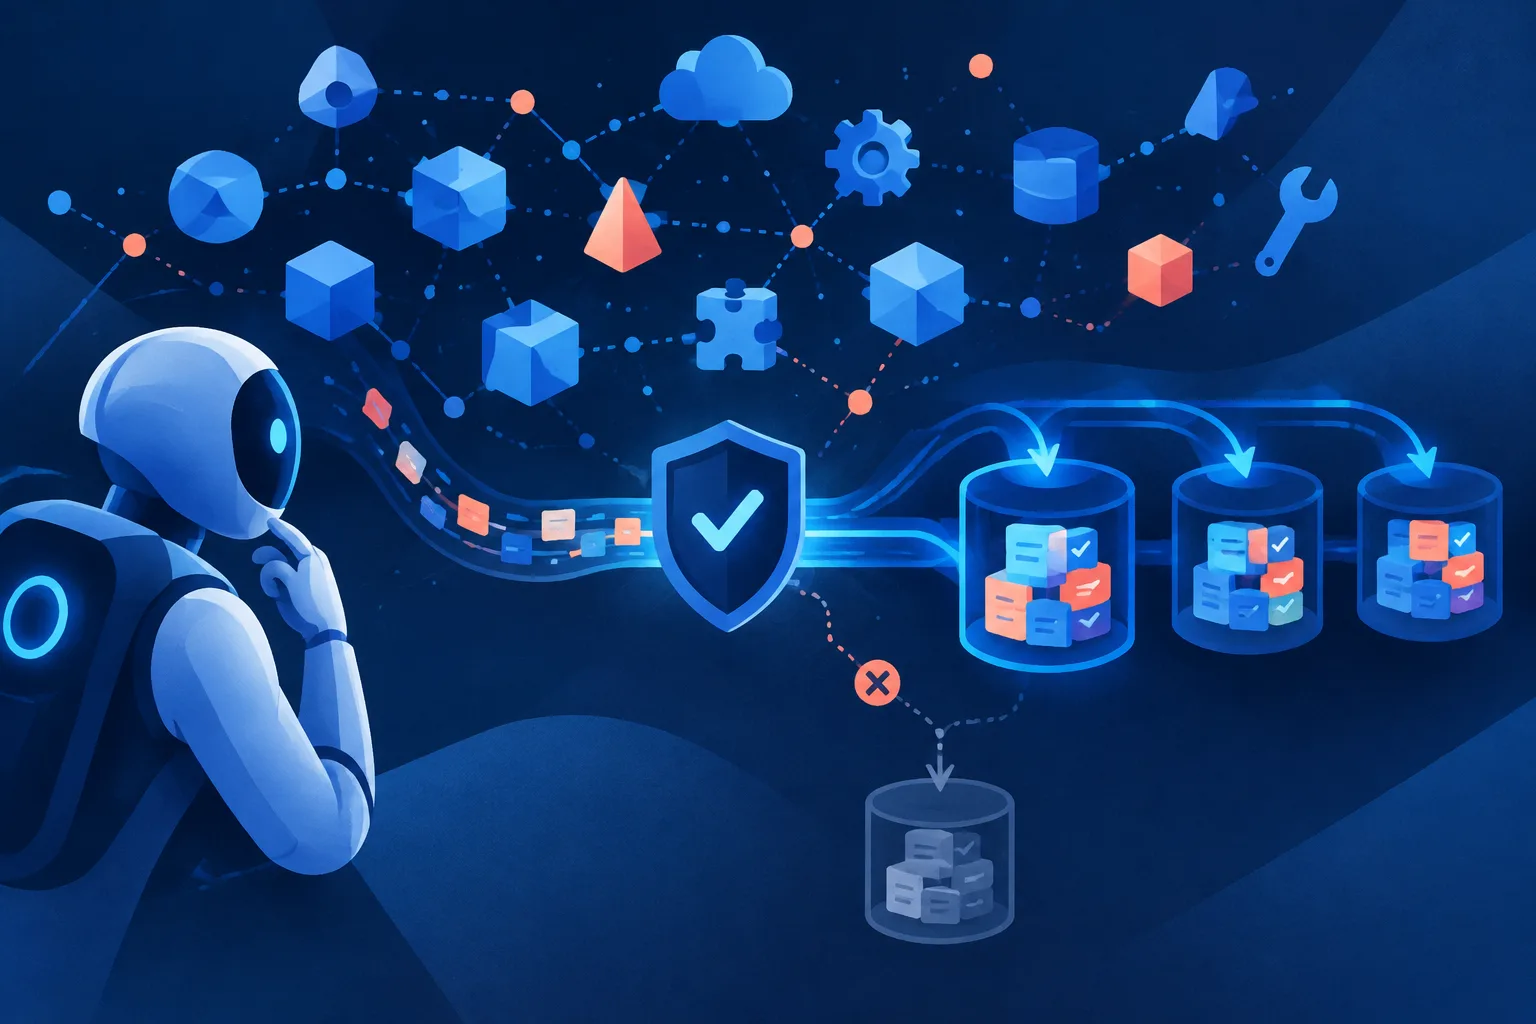
The researchers paired that environment design with a domain-agnostic agent called the Generalist Populator. It receives a registry of tool names, descriptions and input signatures, but no direct database-schema access or hand-written task library. During an initial exploration phase, write operations are blocked while the agent maps entities and dependencies. It records that knowledge in a persistent manifest, then plans concrete population tasks and executes them through the available read and write tools. Shortcuts discovered during execution can be saved as reusable heuristics for later runs.
The team evaluated the system in ten SQLite-backed mock environments spanning airline reservations, human resources, banking, retail, e-commerce, pharmacy, university enrollment, online forums, cloud infrastructure and IT service management. The paper reports a validation pass rate of 1.0 across the environments and an average marginal-distribution fidelity of 0.88. Five domains exceeded 0.93 on that marginal measure. The authors also tested an airline environment with obfuscated names and found similar fidelity, suggesting that the agent could infer much of the dependency structure from tool signatures rather than familiar business vocabulary.
Results were uneven in ways that matter for deployment. Cross-table fidelity was low in the forum and banking environments because the agent misjudged the relative frequency of creation tasks and follow-on activity. It generated too few replies per forum thread and too few transactions per bank account compared with the reference distributions. The paper says this reflects bias in the model's estimates of typical activity when no domain frequency signal is available. The agent was also slow compared with offline tabular generators, taking 41 to 118 seconds per trajectory in the reported tests.
STS was compared with statistical synthesizers and a schema-privileged environment generator. Seven of the ten environments had no seed data, leaving the statistical methods unable to train there. On the airline workflow, the schema-privileged baseline produced no rows in 82% of trajectories because identifiers placed into planned tasks became stale before execution. The Generalist Populator performed better on the airline distribution metrics, although the schema-aware baseline held a small cross-table advantage in the cloud environment and was nearly tied in human resources.
The researchers also ran a small downstream experiment using the synthetic airline state. They generated multi-turn rollouts, retained 19 successful STS examples and 18 examples from the original seed snapshot, and fine-tuned separate Qwen2.5-7B variants. On the paper's airline evaluation, the STS-trained model scored 0.500 on pass-at-k, compared with 0.375 for the seed-trained model and 0.286 for the base model. The sample is limited, but it provides initial evidence that a richer synthetic database state can improve agent training rather than merely pass internal validity checks.
The paper's guarantee has an important boundary: it is only as complete as the enforcement layer. The authors explicitly note that a real deployment would require every relevant business constraint to be encoded at the API boundary, potentially demanding substantial engineering. Their scope also excludes unstructured content and probabilistic enforcement. STS therefore does not eliminate the work of modeling a business system, but it offers a practical separation of responsibilities: APIs protect coherence, while an agent explores the permitted interface and supplies the variety needed for training and evaluation. The authors have released the framework, ten environments and generated datasets for further testing.
Comments
Loading comments…