A new research paper proposes splitting an AI agent’s control loop into three parts so the model doing the work no longer has sole authority to execute actions or declare the job finished. The system, called DeReAct, surrounds a task-solving model with an independent action reviewer and a separate completion checker. Its authors, affiliated with Amazon and Apple, report that the design improved first-attempt performance for weaker models on two agent benchmarks, while producing more grounded work from a stronger model without a clear accuracy gain.
The proposal targets a basic weakness in ReAct-style agents. In that common setup, one model reasons about a task, chooses commands, observes results and eventually decides that it is done. According to the paper, this means the same policy effectively approves its own actions and validates its own completion. A mistaken tool call can shape every later step, while an answer based on incomplete evidence can end the run before the task’s requirements have actually been met.
DeReAct assigns those decisions to distinct modules. The Brain proposes an intent and an executable command. Before anything reaches the environment, a Critic checks the proposed command against configured rules such as syntax, safety and explicit task constraints. A rejected command does not execute; instead, the Brain receives feedback and must try again. The Critic is not intended to judge whether the overall strategy is clever or likely to succeed, only whether the proposed action is permitted under the configured checks.
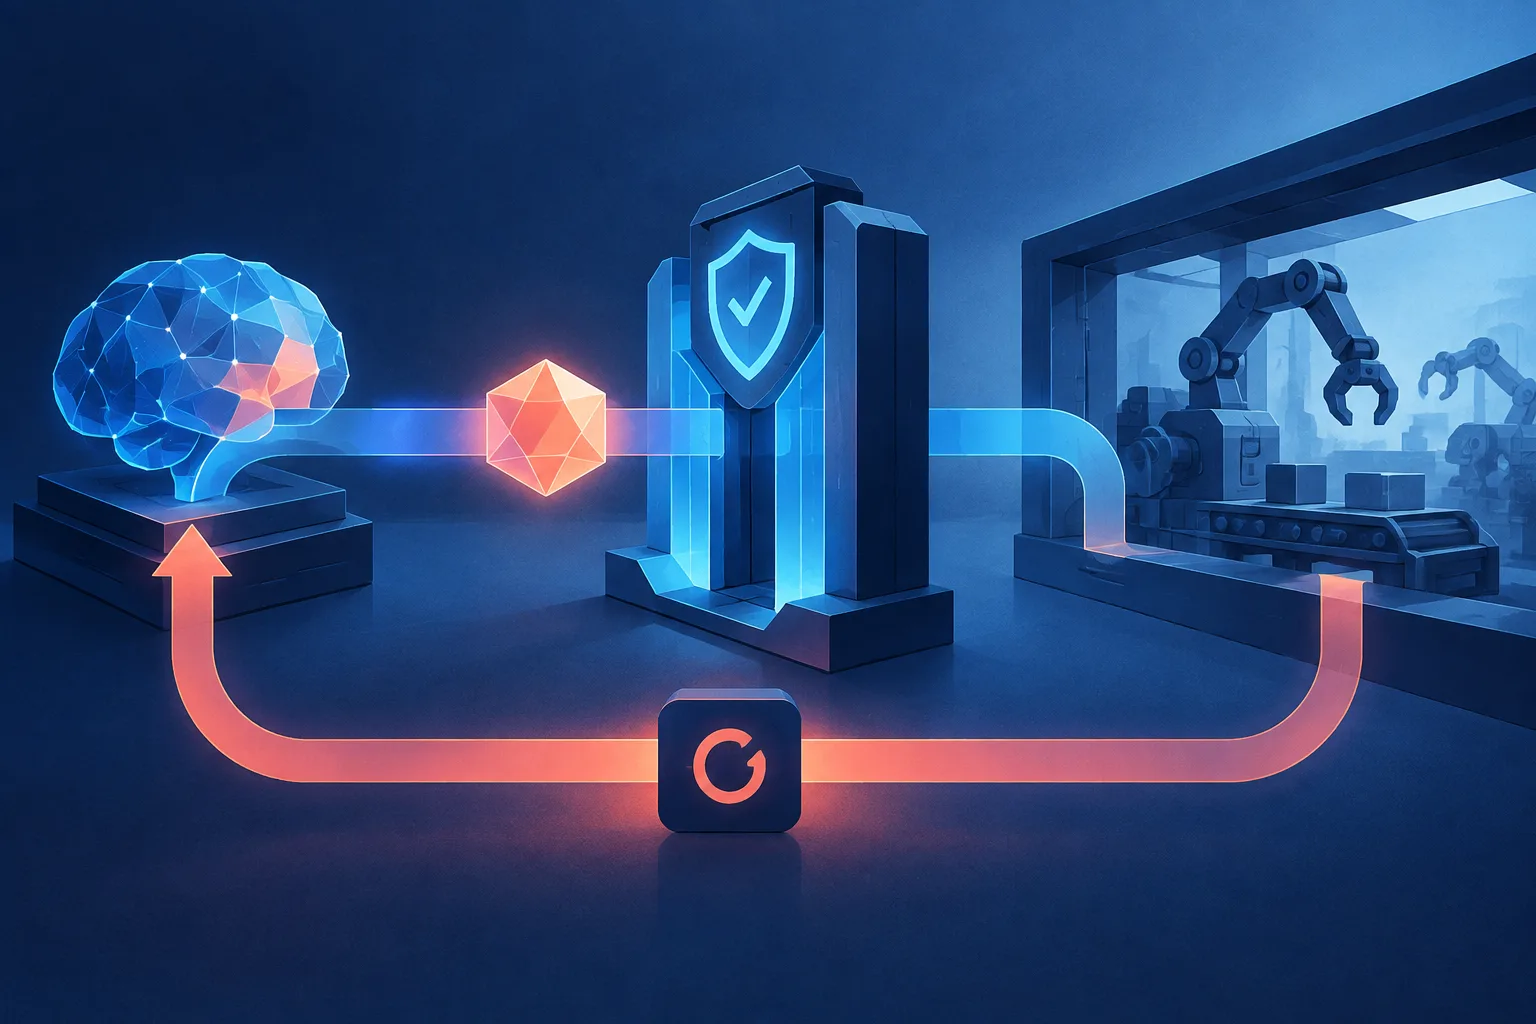
After an approved action runs, a Context Manager rebuilds a compact record using facts supported by the environment. The authors call this record the State. It excludes the Brain’s unverified reasoning and replaces the prior State rather than continually appending to it. The Context Manager also decides whether the available evidence proves that the task is complete. If not, the agent continues even when the Brain has already proposed a final answer.
The researchers compared DeReAct with a conventional ReAct loop on GAIA, a set of 165 retrieval-and-reasoning questions, and on 489 SWE-bench Verified software-engineering tasks supported by the official test harness. They ran three attempts per task with Qwen3-Coder-480B, Claude Sonnet 4.5 and Claude Opus 4.5 as progressively stronger Brain models. A Claude Haiku 4.5 model served as the Critic throughout; Context Manager configurations varied in some experiments.
The largest first-attempt improvements appeared with the weaker Brains. Against ReAct, DeReAct raised Pass@1 by 6.5 percentage points on GAIA and 7.0 points on SWE-bench Verified for Qwen3-Coder-480B. With Claude Sonnet 4.5, the reported gains were 4.2 points on GAIA and 5.2 points on SWE-bench Verified, although the GAIA improvement was not statistically significant under the paper’s test. With Claude Opus 4.5, first-attempt performance was effectively comparable: up 1.0 point on GAIA and down 0.3 point on SWE-bench, both within statistical noise.
The paper argues that accuracy alone misses part of the benefit. For Opus trajectories on GAIA, DeReAct increased the share judged both evidence-complete and constraint-satisfying from 60.1% to 68.7%, while admitted guessing fell from 21.0% to 15.1%. On SWE-bench, appropriate testing rose more modestly, from 78.2% to 80.8%. Those grounding assessments relied on a single Claude Opus 4.7 judge, so they should be read as the study’s operational measures rather than independent proof of reliability.
Extra oversight was not automatically helpful. In one SWE-bench configuration, a Haiku Context Manager vetoed about 93% of Qwen3 final answers yet reduced first-attempt performance by 3.5 points because its reconstructed State and completion decisions were often inadequate. The authors describe this as a policy-sufficiency problem: an external gate needs an appropriate prompt, a capable enough model and access to enough context. A more accurate checker cannot recover evidence that has already disappeared from the Brain’s history window.
The architecture also carries a cost. On GAIA with the Opus Brain, the mean run cost was about 2.9 times that of ReAct, and some failing trajectories became much longer. On SWE-bench, the strongest configurations approached or matched ReAct’s mean cost, which the authors attribute in part to executable tests providing a clearer completion signal. Their accounting used list prices without prompt caching or batching, so production economics could differ.
DeReAct remains an early research result rather than a deployment guarantee. The evaluation covers only GAIA and SWE-bench Verified, not multi-turn conversations, human-supervised workflows or agents taking real-world actions. The Critic and Context Manager were also Claude models in all experiments, while only one open-weight Brain was tested. Still, the study offers a concrete engineering lesson: an agent need not be trusted to approve every action and certify its own success, but the systems checking it must be tested as rigorously as the agent itself.
Comments
Loading comments…