A research paper on modular AI agents argues that learning what usually happens next is not enough when an agent must actively change the state of a system. Authors Xinyuan Song of Emory University and Zekun Cai of the University of Tokyo and LocationMind propose FedCausalCompose, a framework designed to identify causal links between services such as ordering, payment, inventory, and shipping. The paper is a preprint under review, so its findings should be treated as early evidence rather than settled performance claims.
The distinction matters because an observational record can be misleading. A transaction log may show that payment occurs before shipping, but sequence alone cannot establish whether payment authorizes shipment, inventory mediates the relationship, or an unseen trigger caused both events. An agent trained only on those traces may predict familiar sequences while failing when asked to intervene—for example, by changing a payment or inventory state and then deciding which downstream action remains valid.
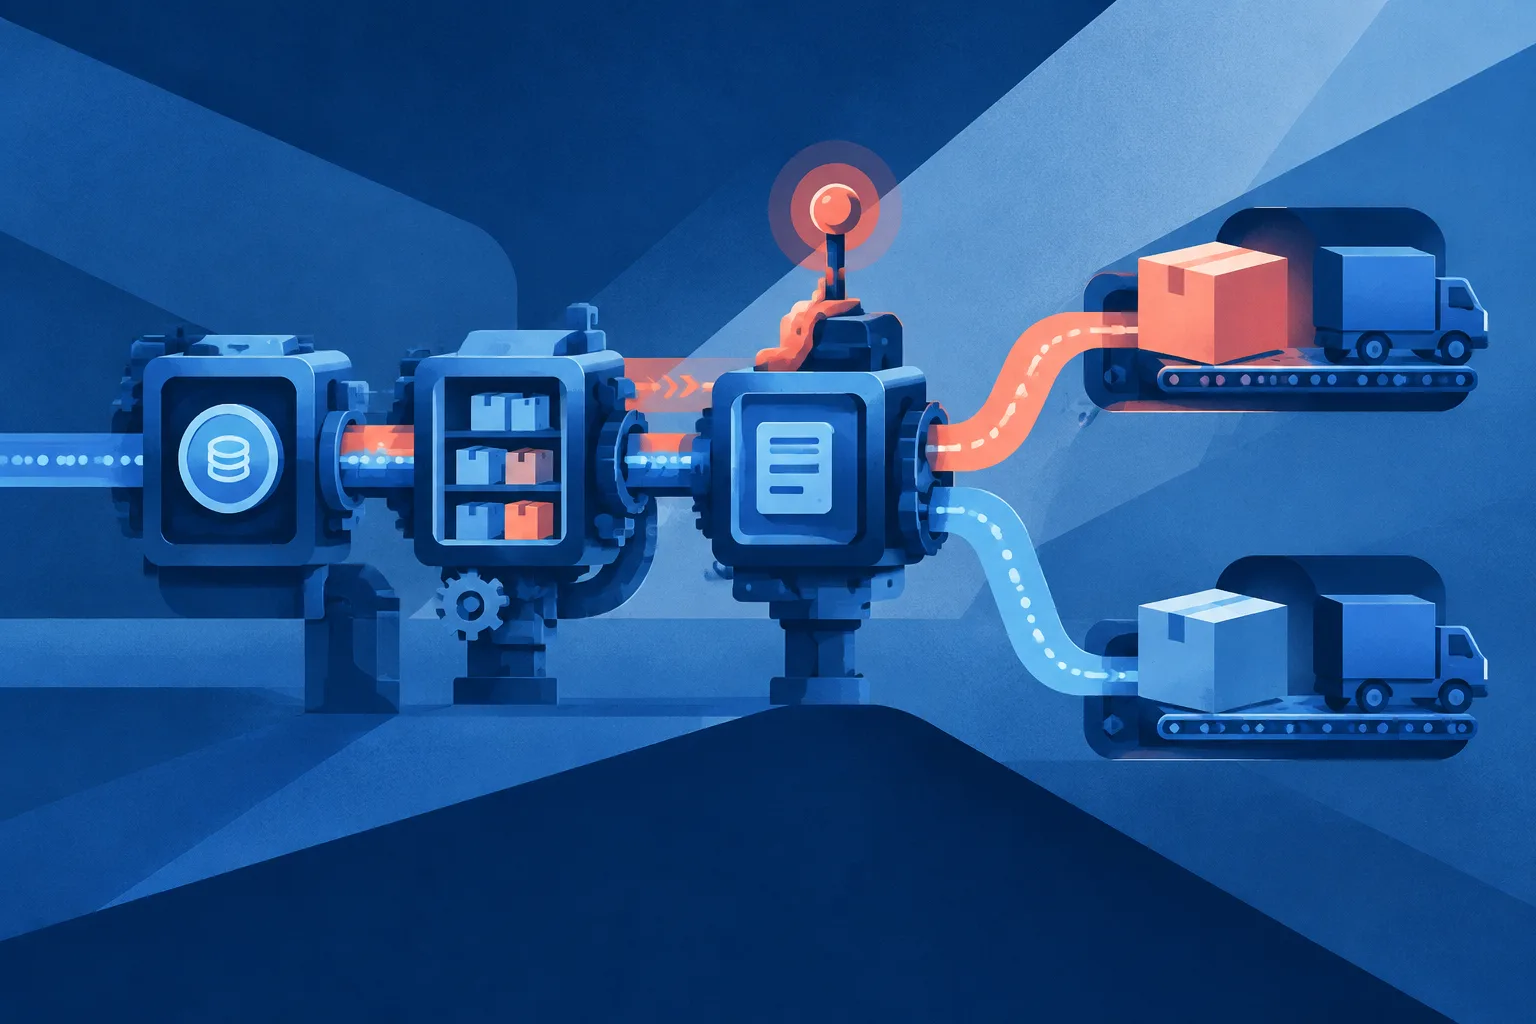
FedCausalCompose treats each service as a functional module with its own state, actions, and interfaces. The proposed process identifies variables and interface events, matches local interventions with downstream responses, validates links between modules, and composes the local mechanisms into a larger causal world model. The authors envision modules sharing intervention-response summaries rather than all raw traces or model parameters, although the experiments in the paper use a centralized prototype rather than a complete privacy-preserving federated system.
The paper’s theoretical analysis says an observational model retains an irreducible error when an unobserved factor creates an open back-door path between an action and a later result. More passive data cannot eliminate that gap if the model has learned the wrong conditional relationship. The authors also argue that errors can compound across a chain of modules, because an incorrect prediction at one interface changes the state seen by every later component.
The experiments add an important qualification: possessing a correct causal graph does not guarantee that a language-model agent will act on it. The authors report that causal interfaces were most useful in structured tool environments, where typed API arguments, visible preconditions, and explicit verification steps already resemble the way an agent selects actions. In that setting, causal links can identify which upstream condition must be satisfied before a downstream operation makes sense.
Dialogue and narrative environments were harder. In tests involving environments such as ALFWorld, tau-bench dialogue, and SciWorld, raw lists of causal edges often competed with the goal, conversation history, and tool descriptions for the model’s attention. A short attention anchor that made the causal information relevant to the immediate decision could help, according to the paper. The result suggests that causal information must be both statistically identifiable and presented in a form the model will use at the exact moment of choice.
The authors are explicit about the limits of their evidence. Most agent experiments are single-seed point estimates, several uncertainty intervals are wide, and the current modular boundaries and oracle edges were designed by the researchers. AndroidWorld testing was deferred because the required emulator was unavailable. A production version would also need privacy accounting, secure aggregation, communication constraints, asynchronous updates, and a less supervised method for discovering module boundaries and delayed effects.
The practical message is narrower than a claim that causal models broadly solve agent reliability. FedCausalCompose provides a way to distinguish genuine intervention effects from correlations across connected services, but the graph must be sufficiently supported by intervention data and operationally visible to the agent. For developers, the paper points to two separate engineering problems: learning the right causal dependencies and designing the tool or prompt layer so those dependencies influence the next action.
Comments
Loading comments…