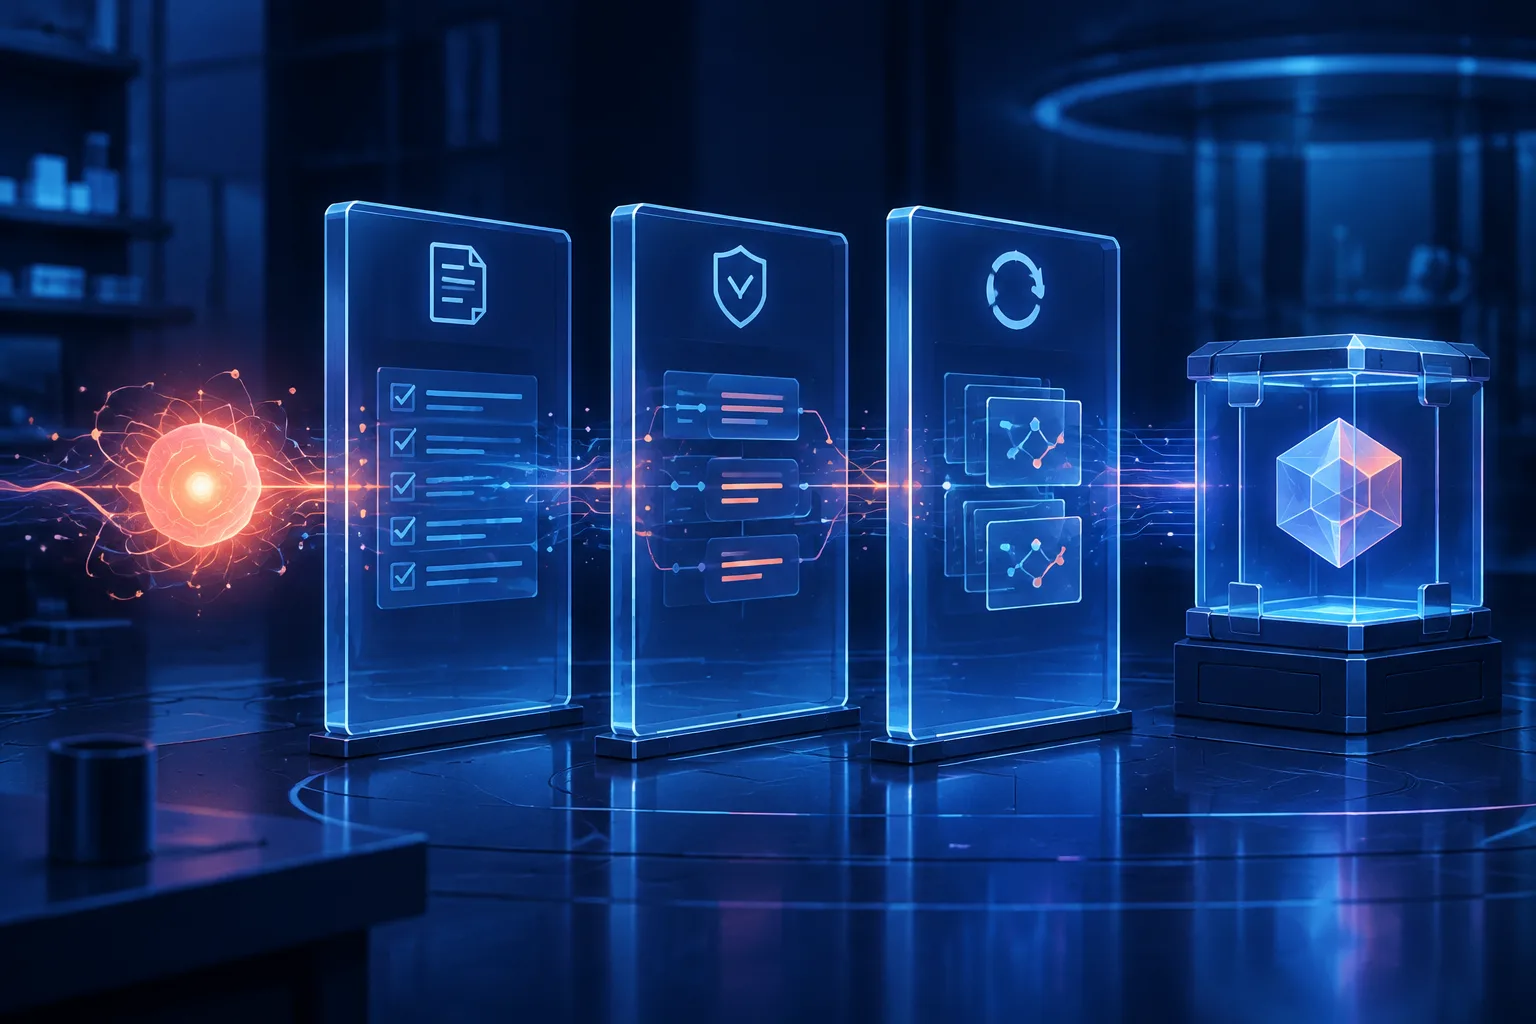
A new research-agent architecture called EPOCH is built around a blunt premise: finding a promising program, construction or proof is not the same as establishing a discovery. In a preprint submitted to arXiv on October 4, Binjie Guo, Aisheng Mo, Ruitong Li and Xinle Deng argue that AI systems need an explicit process for deciding what evidence a result requires, how that evidence can be challenged and what the resulting claim is actually allowed to say.
EPOCH stands for Evidence-conditioned Proposal Optimization through Cumulative Hypothesis-governance. Each task begins with a contract that defines the permitted edits, available checks, resource limits, data views and acceptable claim scope. The system then keeps an append-only, typed record of successful and failed trials rather than reducing every attempt to a single reward. A proposal can include a candidate, a hypothesis about why it should work, a predicted effect, references to prior evidence and an intended way to falsify it.
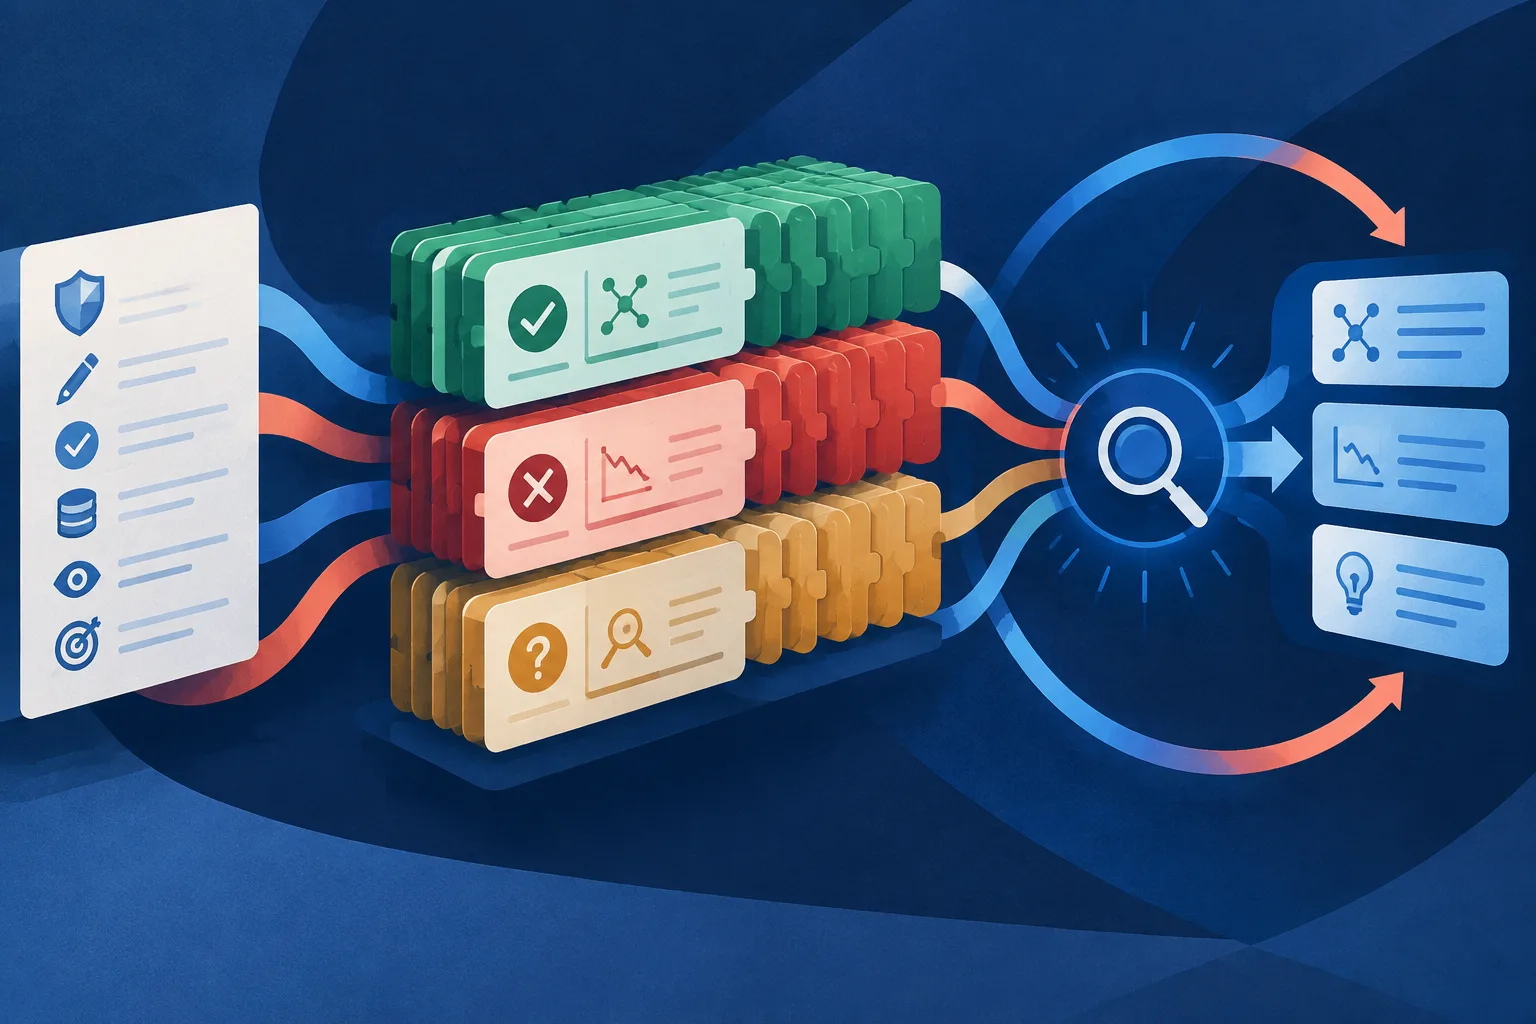
That structure changes what happens after an apparently good score. EPOCH challenges a candidate against its stated mechanism, applies admission gates and then replays the frozen endpoint independently. A finite computation is not promoted into a universal theorem, and an unresolved check is not treated as a pass. The authors describe the resulting seal as a binding record of the task contract, selected artifact, evidence ledger, claim and scope. The architecture is therefore less a universal verifier than a protocol for keeping domain-specific verification attached to the result it supports.
The paper reports its broadest benchmark comparison on a frozen 12-task subset of AlgoTune. Five methods received the same budget of 48 semantic calls and were run with three seeds. EPOCH reached a mean normalized development score of 0.65, compared with 0.53 for the strongest baseline, AdaEvolve. The researchers also froze eligible final programs and replayed them on 32 previously unused official test inputs. EPOCH had positive mean effects against all four baselines across the seven replayed tasks, although one task, nonnegative matrix factorization, reversed in the held-out evaluation.
On the authors' internal Math14 suite, EPOCH posted the highest mean score at 0.57, narrowly ahead of OpenEvolve at 0.56. An ablation study across six AgentHPOBench tasks also gave the complete system the highest descriptive normalized mean. Removing memory, proof admission, falsification or the phase controller lowered that aggregate, but the paper notes an important trade-off: the no-memory variant did better on two individual tasks, suggesting that preserving past evidence can improve coverage while constraining short-horizon exploration.
The case studies are where the governance idea becomes concrete. The authors report an executable procedure for selecting the median of 23 elements in at most 54 comparisons, one fewer than the classical 55-comparison construction. They also describe an AES reversible-circuit rewrite that shares intermediate factors, reducing the T-count from 10,746 to 9,234 under matched PyZX synthesis while checking all 256 inputs and restoring every ancilla. In mathematics, the system produced a Lean-checked hypercube determinant inequality with an equality classification and a nine-element counterexample to a proposed coefficient ordering, which the authors extend to an infinite family.
Those outcomes do not all carry the same evidentiary weight, and the paper makes that distinction part of its contribution. Some results have exact coordinates or executable certificates; some include Lean-checked statements; others retain an open bridge between a verified core and a broader source claim. The authors say specialist review, statement alignment and priority assessment are still required. They also call for larger paired evaluations, fixed budgets and fuller resource accounting, while identifying simulations, experiments, databases, instruments and expert interaction as future settings for the protocol.
EPOCH's consequential idea is not simply that an AI agent can search harder. It is that the search loop should preserve failures, invite targeted refutation and prevent a score from silently expanding into a claim the evidence cannot bear. The reported benchmark gains and technical cases remain preprint results that need independent scrutiny, but the architecture offers a concrete answer to a growing problem: as AI systems generate more research candidates, the machinery for qualifying those candidates must become part of the system rather than an afterthought.
Comments
Loading comments…