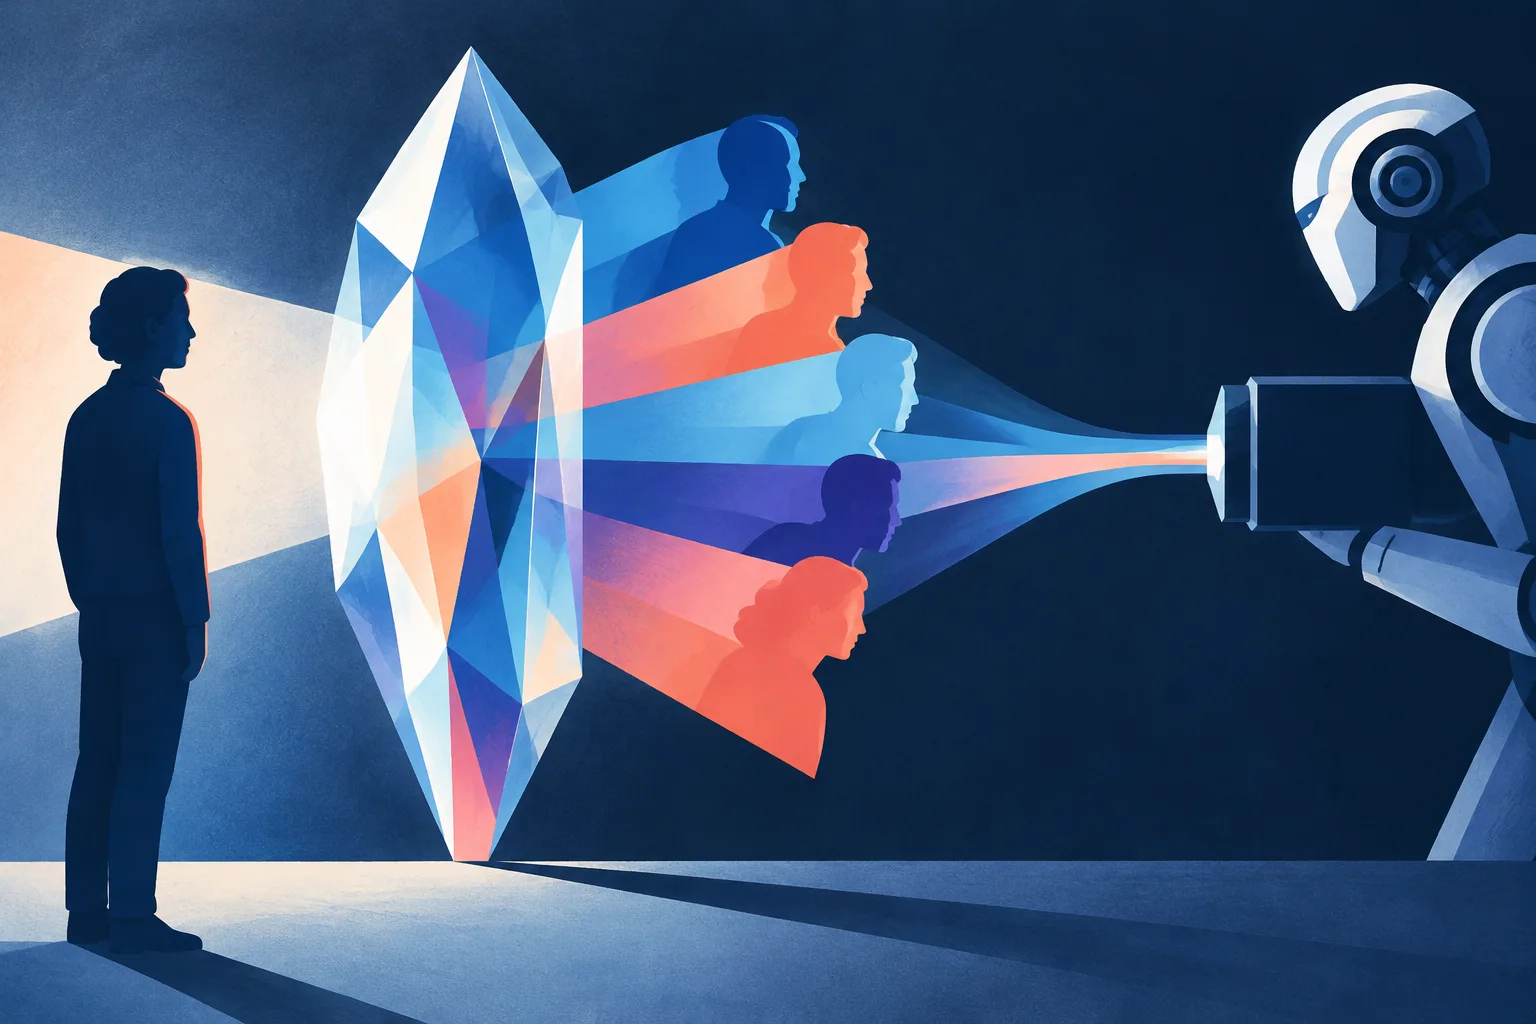
Many AI systems are trained as if every question ultimately has one correct answer. For object recognition or speech transcription, that assumption may often be useful. But a new position paper argues that it breaks down when models are asked to interpret emotions, moderate speech, infer intent or support decisions about people—domains where several readings can be reasonable at the same time.
The paper, submitted to arXiv on October 7 and accepted to the NeurIPS 2026 Trustworthy AI for Good Workshop, comes from researchers affiliated with MIT, Novo Nordisk, Copenhagen Business School and Aalborg University. It is not an experimental study claiming a finished technical solution. Instead, it proposes a framework for treating ambiguity as a core feature of human-centered AI across data collection, training, evaluation, deployment and governance.
The authors distinguish meaningful ambiguity from ordinary annotation noise. Ambiguity can reflect differences in culture, expertise, context, personal experience, geography or changing social norms. Noise comes from mistakes, inattentive labeling, unclear instructions or degraded inputs. Their central warning is that majority voting and averaging may erase valuable information when they treat both forms of variation as the same problem.
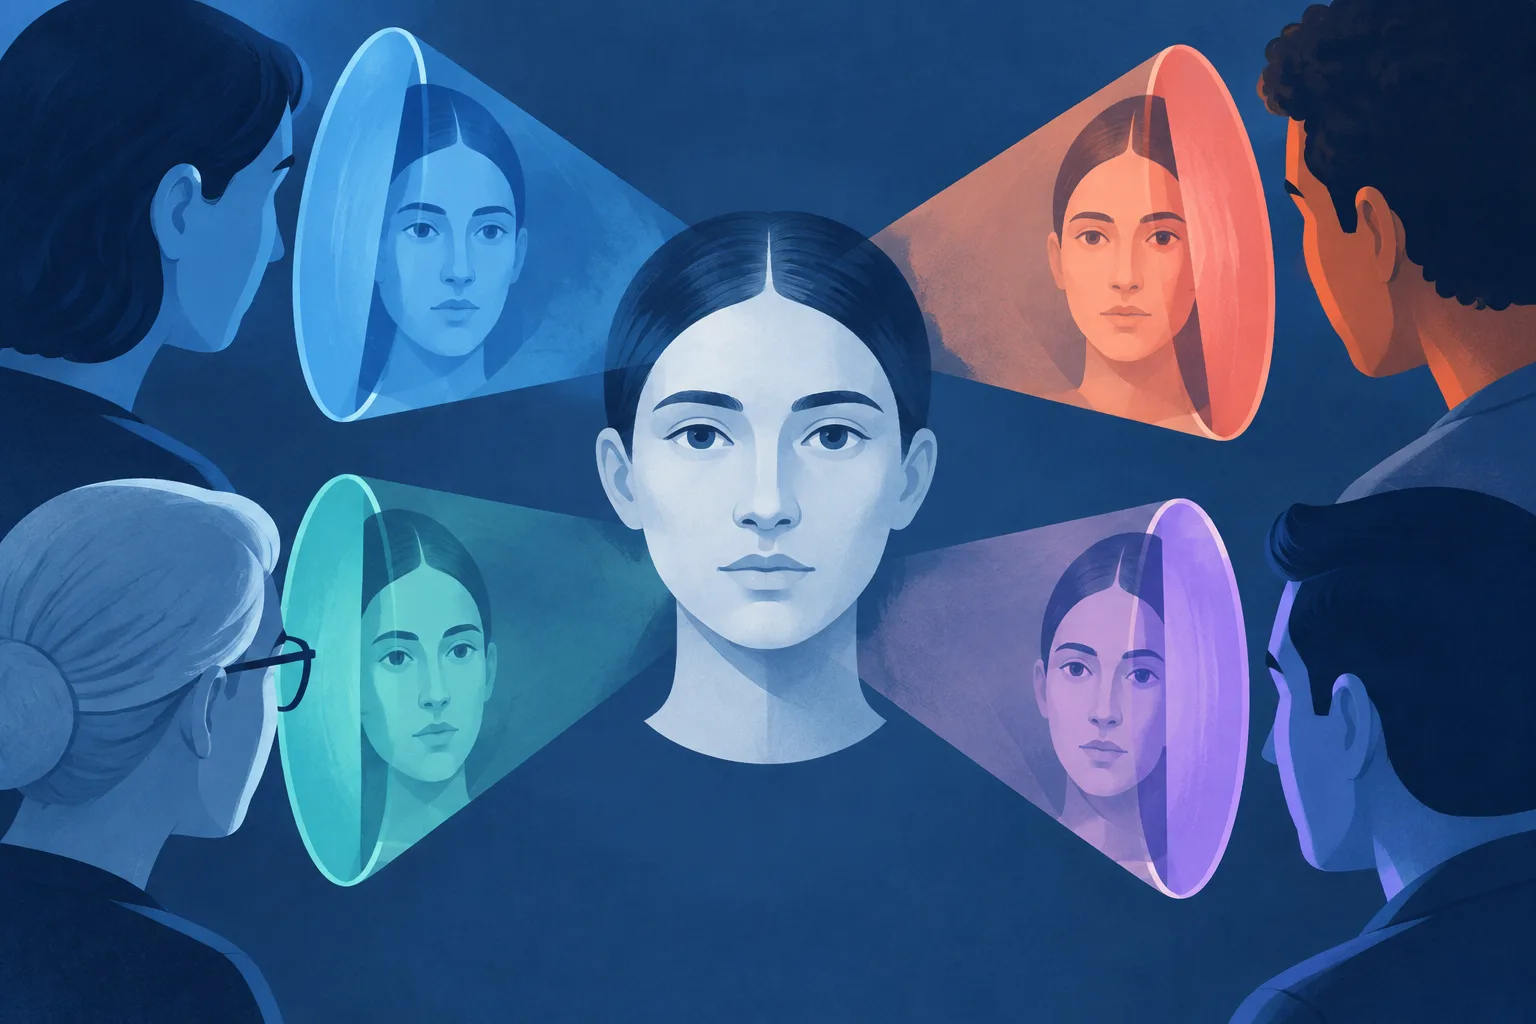
A facial expression illustrates the difference. The same look might reasonably be read as anger, stress, concentration or discomfort, depending on context. A mistaken click on the wrong label is noise; a coherent alternative interpretation is not. The paper argues that AI developers should reduce the former while preserving the latter as part of an “interpretation space” containing multiple plausible human judgments.
That distinction becomes consequential when model outputs guide action. In content moderation, a majority may view a post as harmless while members of the targeted group consistently perceive harm. The minority judgment can therefore carry information that a single aggregate label hides. In robotics, uncertainty about whether a person is handing over an object, repositioning it or taking it back may determine whether physical action is safe.
Healthcare supplies another example. Clinicians can reasonably disagree about the severity or significance of the same patient-reported symptoms because their expertise and contextual understanding differ. The paper suggests that an ambiguity-aware system could preserve those assessments and communicate multiple plausible interpretations instead of presenting a single label as uncontested fact. The authors also stress that higher-risk settings require narrower operational boundaries, stronger evidence and more human oversight.
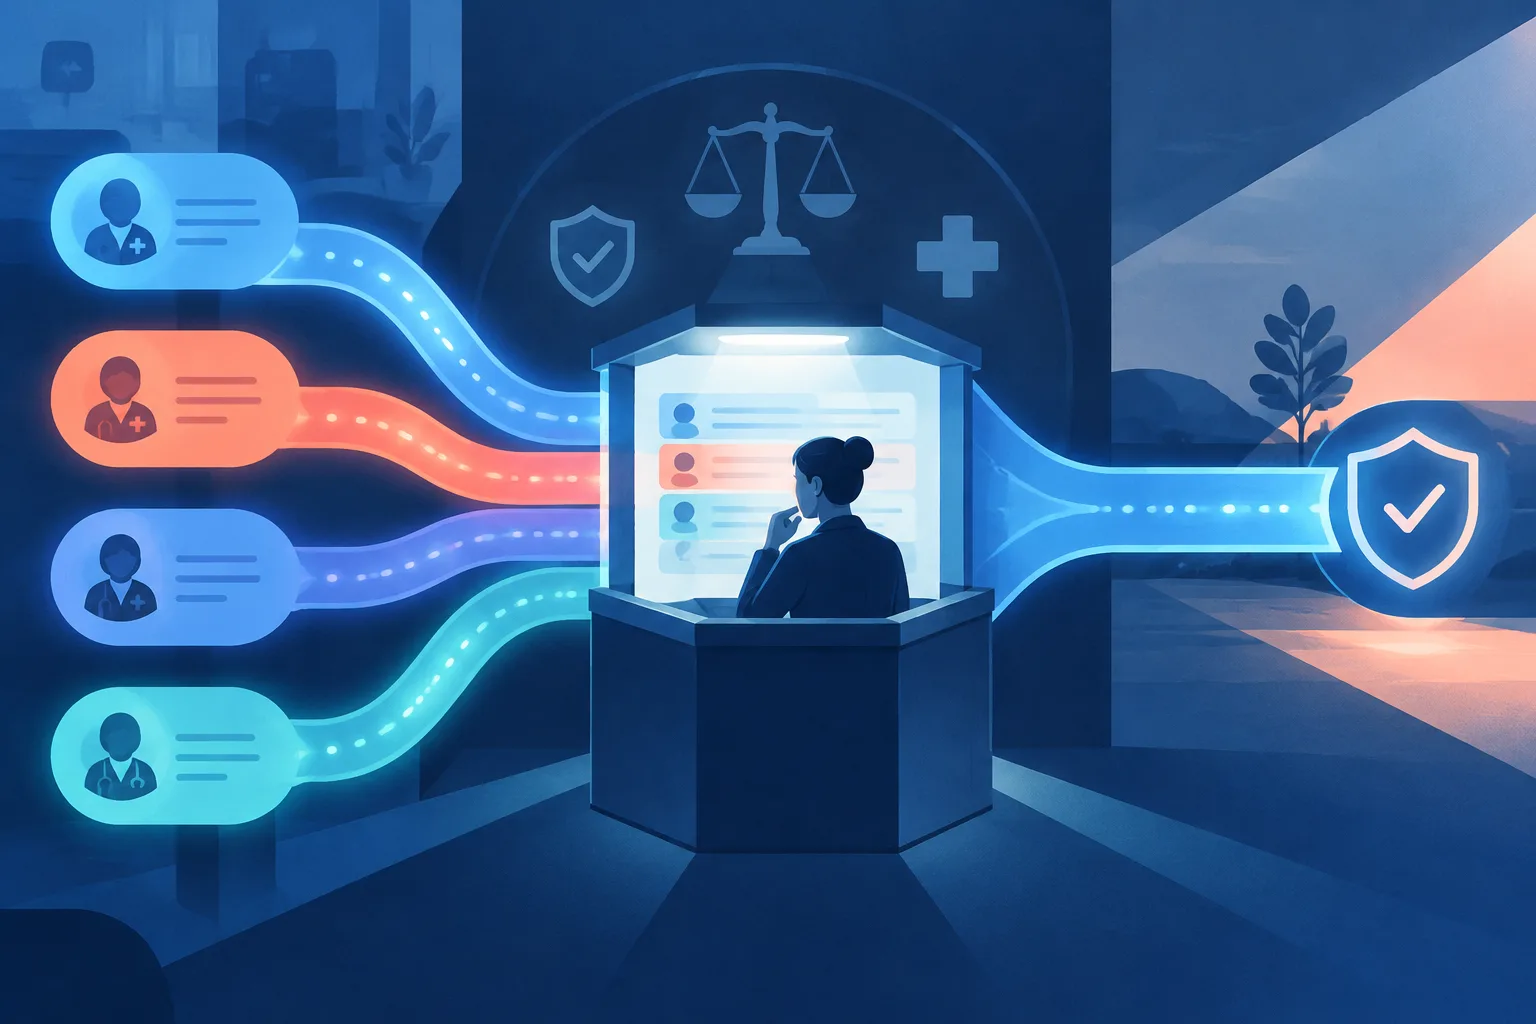
The proposed framework changes three stages of model development. Representation should retain distributions, sets of valid labels, annotator-specific patterns or other signals of interpretive diversity. Training objectives should learn from meaningful disagreement while remaining robust to annotation artifacts. Evaluation should then test whether outputs reflect the relevant interpretation space, rather than measuring accuracy against one flattened target.
Governance would also need to track what the authors call “subjectivity drift”: legitimate interpretations can change as cultures, organizations, regulations and professional practices evolve even when the underlying input data remains stable. Suggested monitoring mechanisms include re-annotation, stakeholder feedback, expert review and calibration exercises. A changing interpretation space may call for a model update, whereas rising annotation noise points to data-quality and process problems.
Preserving disagreement does not mean every interpretation is acceptable. The paper separates empirical subjectivity from normative constraints such as law, ethics, organizational policies and domain standards. Its authors argue that systems can represent how people genuinely differ while still being constrained in how they act. They also contend that minority views may expose harms, demographic disparities and cultural blind spots that majority aggregation can conceal.
The proposal leaves a difficult technical question unresolved: it does not prescribe an algorithm for reliably separating legitimate ambiguity from noise. That boundary can itself be contested, especially when annotator identities, power and deployment context shape what counts as plausible. Still, the framework offers a concrete test for human-centered AI: before training toward one label, developers should ask whether the disagreement in the data is an error to remove—or part of the reality the system is supposed to understand.
Comments
Loading comments…