Letting an AI agent improve itself sounds efficient until the system operates inside a regulated credit pipeline. If it changes its own behavior to reduce complaints or false alarms, a supervisor still needs to know exactly what changed, why it changed, how it was tested and whether the fix created a new class of errors. A new preprint proposes a strict answer: keep model weights fixed and allow adaptation only in the surrounding software harness, where every change can be recorded as a reviewable diff.
The paper, submitted to arXiv on October 7 by Ravil Akhtyamov of Digital Economy Lab, tests that idea in a synthetic credit-compliance environment. It has not been peer reviewed. Crucially, neither the simulated agent nor the system proposing changes was a language model. The agent followed deterministic rules, while a seeded search selected from a predefined edit space that already contained the correct replacement component.
Within those limits, the experiment examined whether an admission gate could prevent apparently helpful adaptations from weakening the screening system. The design allowed a local loop to adjust a parameter or clause and a global loop to replace a named primitive from a typed library. Both routes passed through the same gate, which required statistically supported improvement and limited regression on cases the existing harness already handled correctly.
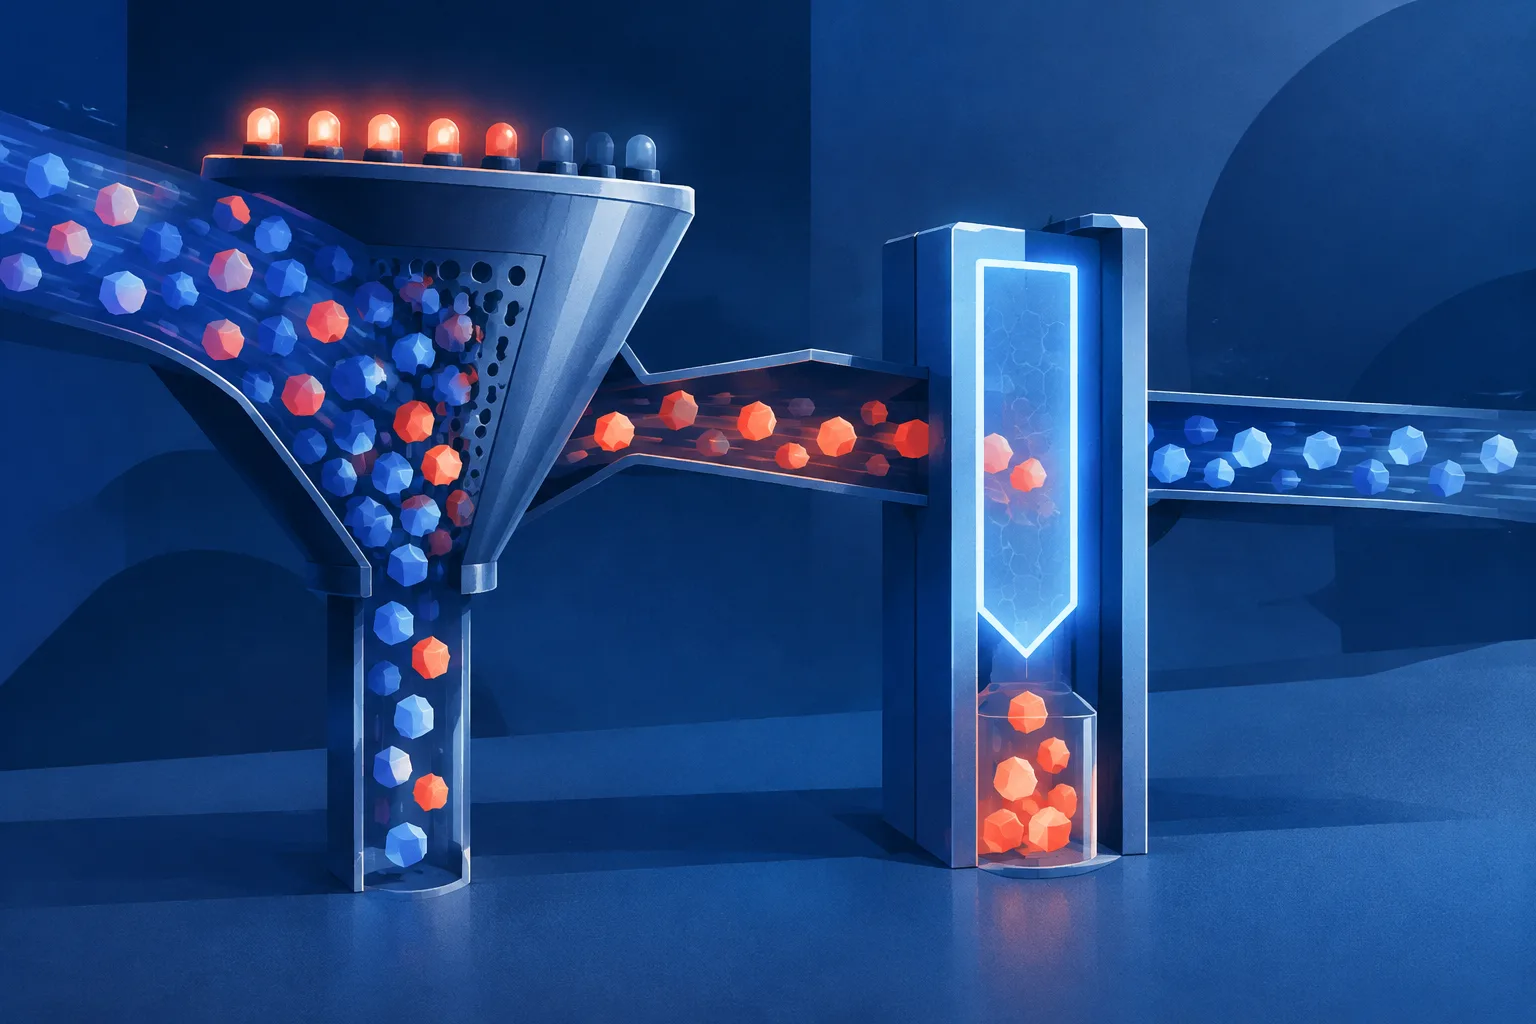
That control mattered because the operational feedback was deliberately asymmetric. Every flagged case was reviewed, making false positives visible, while only 5 percent of cleared cases were audited, leaving most missed flags unseen. A system optimizing only the errors visible in recent traces could therefore make its dashboard look better by flagging fewer cases, even when that meant allowing risky cases through.
Across 90 runs covering three kinds of supervisory rule changes at three severity levels, the gated dual loop proposed 7,449 candidate changes and admitted 144. The paper reports that none of those admissions increased true error on its held-out audit split, and the final missed-flag rate stayed below 10 percent in every run. In the low- and medium-severity conditions, the system restored false-positive performance to the simulated oracle level without increasing missed flags.
Removing the gate produced a much worse trade-off. The same loops, using a simple check for fewer errors in recent traces, admitted 550 changes; 309 increased error on held-out history. Missed flags finished above 10 percent in 49 of 90 runs. In the medium scope-change condition, the no-gate system matched the oracle’s false-positive rate but reached a mean missed-flag rate of 79.7 percent—an apparent improvement produced largely by loosening the screen.
The paper also finds that adaptation fails when it is tested against obsolete labels. A version of the gate using labels from before the supervisory reinterpretation rejected all 8,490 candidates, including the exactly correct harness hundreds of times. The proposed solution requires people to encode the new supervisory rule and use it to relabel stored cases. The search for a harness edit can then be automated, but the target remains set by an accountable human function.
Every candidate decision is written before deployment into an append-only, hash-chained log that names the cause, the proposed diff, test results and the harness digests before and after. The author argues that this makes harness changes auditable and reversible in a way that continuous weight changes are not. The paper is careful to say this does not guarantee reproducible behavior from a hosted model, which can still change because of provider updates, decoding settings, tools or retrieval state.
The gate was not flawless. Under the most severe structural change, its fixed non-regression tolerance blocked the correct primitive replacement in half the seeds. Doubling that tolerance in a separate sensitivity test recovered all ten seeds without a false admission, but the study did not measure the protective trade-off under a setting where harmful candidates might also pass. The author suggests replacing the fixed threshold with one scaled to expected execution noise.
The regulatory discussion is framed as a design argument, not a compliance opinion. The paper maps the approach to EU AI Act requirements for high-risk credit systems, record-keeping and predetermined changes, while identifying missing evidence for bias monitoring and human oversight. It also notes that no examiner reviewed the artifacts. The next test is larger than this simulation: replace the seeded proposer with an actual LLM, introduce free-text edits and determine whether an auditable boundary survives contact with a genuinely generative agent.
Comments
Loading comments…