An AI system can look better for several very different reasons: it may search longer, receive more help, or face a looser test of whether its answer is correct. A new theoretical paper argues that those possibilities must be separated before researchers describe an agent as having improved itself. In “Verification and Self-Improvement in Agentic AI: Foundations and Limits,” Chien-Ping Lu proposes a formal framework for tracking what an agent can discover, what evidence it may submit, and what its verifier will accept.
The distinction matters because a rising benchmark score is not, by itself, evidence that an agent has acquired a new capability. Lu defines an agent’s “native reach” as the tasks it can get accepted under default support. A broader “closure frontier” includes tasks it can get accepted with any support already allowed by the interface. More search attempts can raise the chance that the agent finds an acceptable answer without changing either boundary. Making optional feedback routine can expand native reach while leaving the frontier unchanged. The frontier grows only when the system admits evidence or interaction transcripts that were previously unavailable.
This accounting becomes especially important when the checker is randomized. A wrong answer may occasionally pass because of a favorable random draw. If a system treats success on any one verifier run as proof, repetition can make false acceptance more likely rather than less. Lu gives a simple example: with a one-in-four false-pass probability on each independent call, accepting if any of three calls passes produces a 37-in-64 chance of at least one false acceptance. Requiring a majority instead cuts the error probability to 5-in-32.
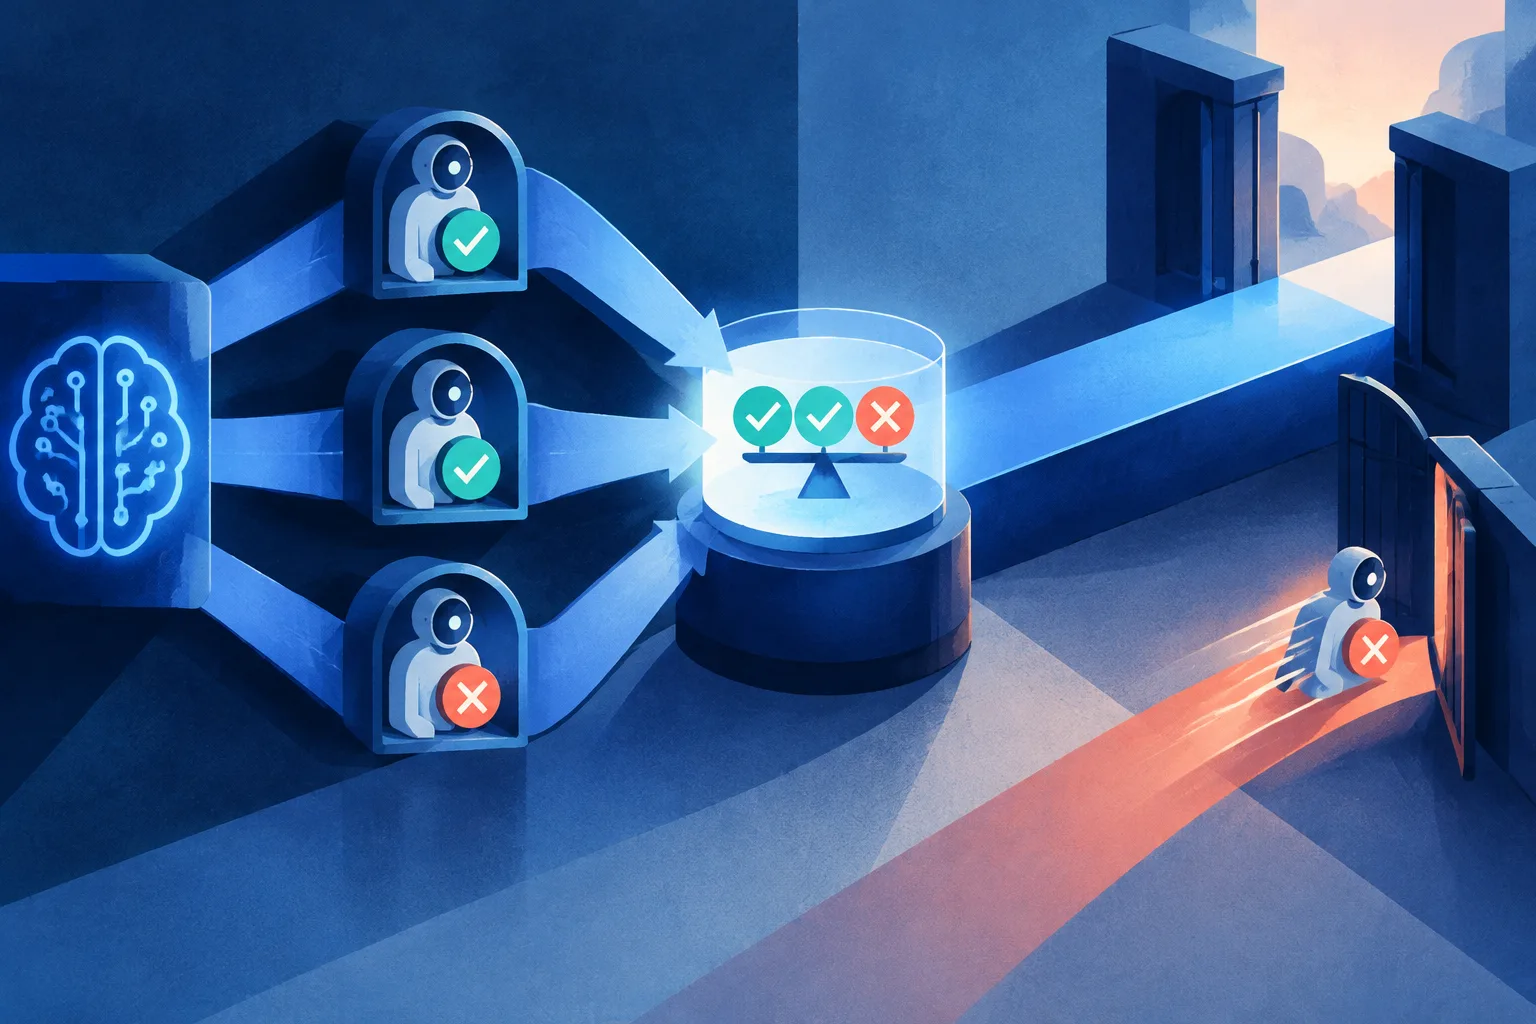
The paper proves a broader amplification result for independent majority voting when the verifier has a pointwise gap between correct and incorrect cases. Under the paper’s assumptions, the error decreases exponentially, with a bound of e to the power of negative N over 18 after N repetitions. The conditions are doing real work: the calls must be independent, the aggregation rule must be sound, and the guarantee must hold for each relevant instance rather than merely on average.
That warning carries over to AI-based judges. A learned evaluator can post strong aggregate accuracy or calibration numbers while still being confidently wrong on a particular subset of cases. The paper therefore cautions that benchmark-level performance does not establish the pointwise soundness needed for a proof-like verifier. Fresh randomness in an agent’s decoding also does not solve adaptive overfitting when the same benchmark is reused.
Lu places these ideas inside a complexity-theoretic model. For verifier protocols with a fixed number of alternating existential and universal choices, the accepted problems lie between adjacent levels of the polynomial hierarchy. The paper does not claim unconditional separations between those levels; stronger statements would require explicit complexity assumptions. Its goal is to classify what a verification interface permits, not to show that present-day agents empirically occupy one exact class.
The same boundary applies to recursive agents that rewrite or select successor systems. If every successor is interpreted by a common sound mechanism, uses the same protocol and quantifier depth, and obeys uniform resource and error-gap limits, recursive self-modification remains within the same verification class. In other words, a system can change its internal policy without automatically gaining a more powerful standard of proof.
Self-improvement also creates a second source of risk: adaptive selection. When an agent evaluates many candidate successors and chooses among them, errors can accumulate across the selection process. The paper states that if there are at most M selection calls and each has a conditional bad-selection probability delta i, the overall probability is bounded by the sum of those deltas. That bookkeeping is separate from the error of the final verifier and cannot be erased by reporting only the performance of the chosen model.
The work is theoretical, not an empirical validation of deployed AI systems. It leaves open practical questions involving distribution shift, correlated verifier failures, and learned judges whose guarantees are average-case rather than pointwise. Still, its central test is concrete: claims about stronger agents should specify what counts as correctness, which evidence and interactions are allowed, what resources the agent used, and how selection error was controlled.
That framing makes “self-improvement” a claim about an entire protocol, not simply a model’s score. An agent that searches harder may be more useful. One that receives better scaffolding may solve more tasks in practice. But neither result proves that the boundary of verifiable capability moved. The paper’s contribution is a vocabulary—and a set of formal limits—for telling those stories apart.
Comments
Loading comments…