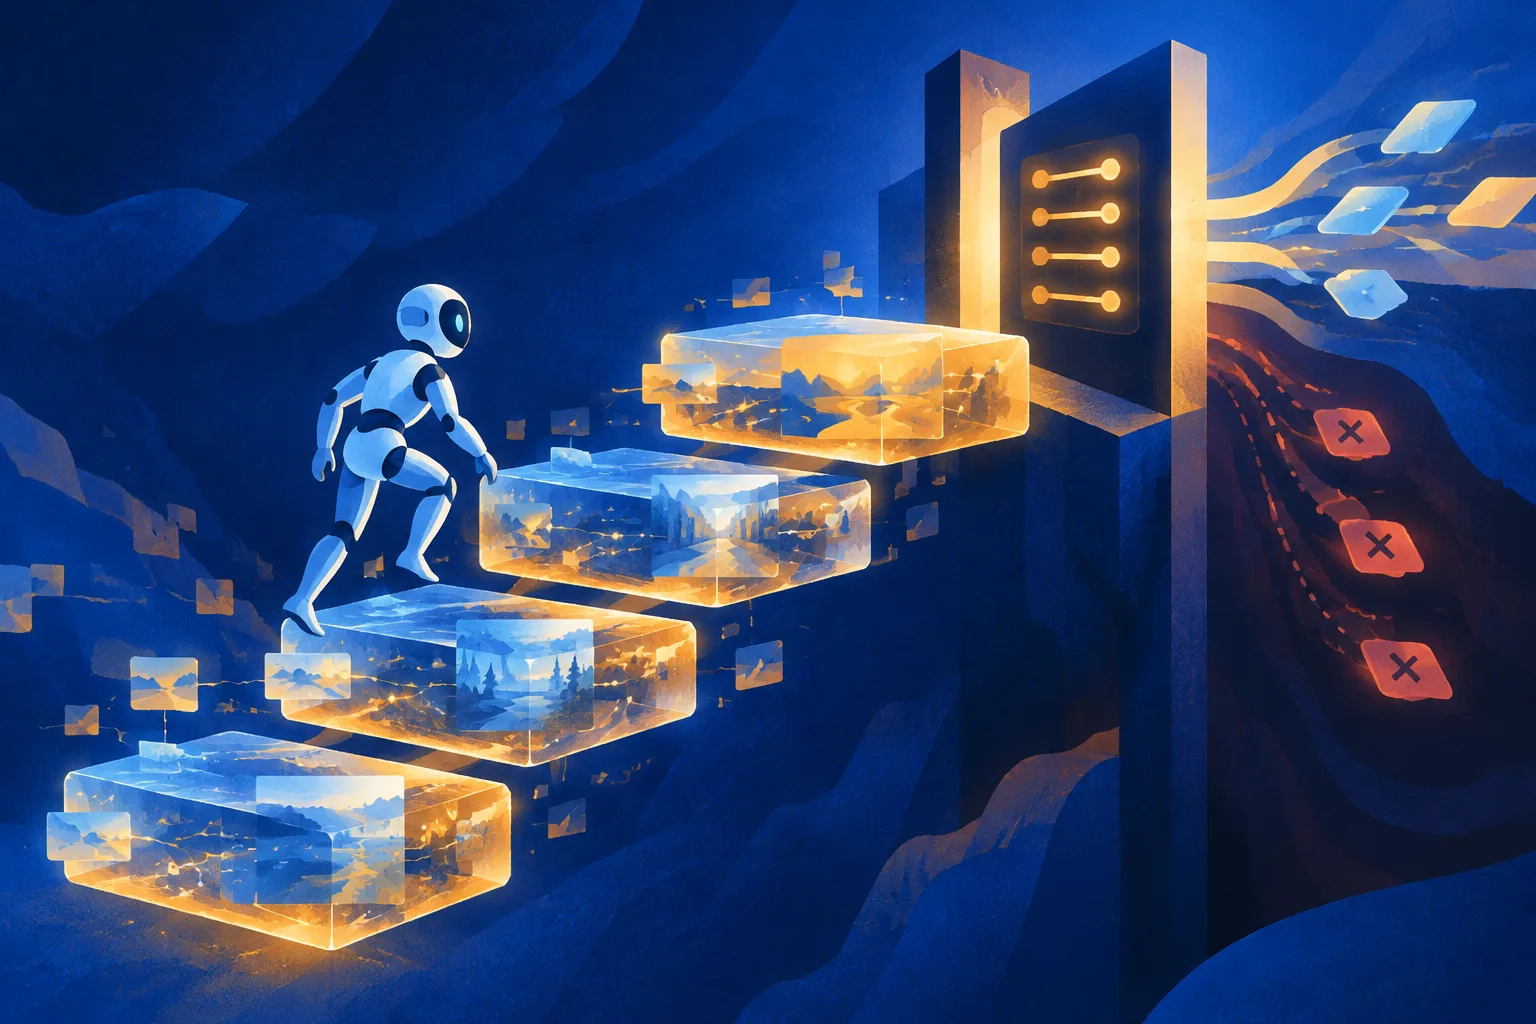
A new agent-memory framework called SAGA attempts to move beyond saving old interactions and replaying them as examples. In an arXiv preprint submitted October 3, researchers Bowen Ye, Yongchao Xu, Junkai Ma, Xiang Yin and Wenzhao Li describe a system that turns execution histories into increasingly abstract knowledge, while preserving links back to the experiences that support it. The goal is to help language-model agents improve after deployment without requiring every adaptation to change the underlying model.
SAGA organizes memory into four levels. Raw trajectories preserve observations, actions and environmental feedback. Episodic records compress individual attempts into their goals, important steps, outcomes and obstacles. Procedures combine related episodes into reusable strategies. At the top, principles state a condition, expected effect, mechanism, scope and exceptions. Links between adjacent levels are meant to keep a broad rule traceable to the concrete runs from which it was inferred.
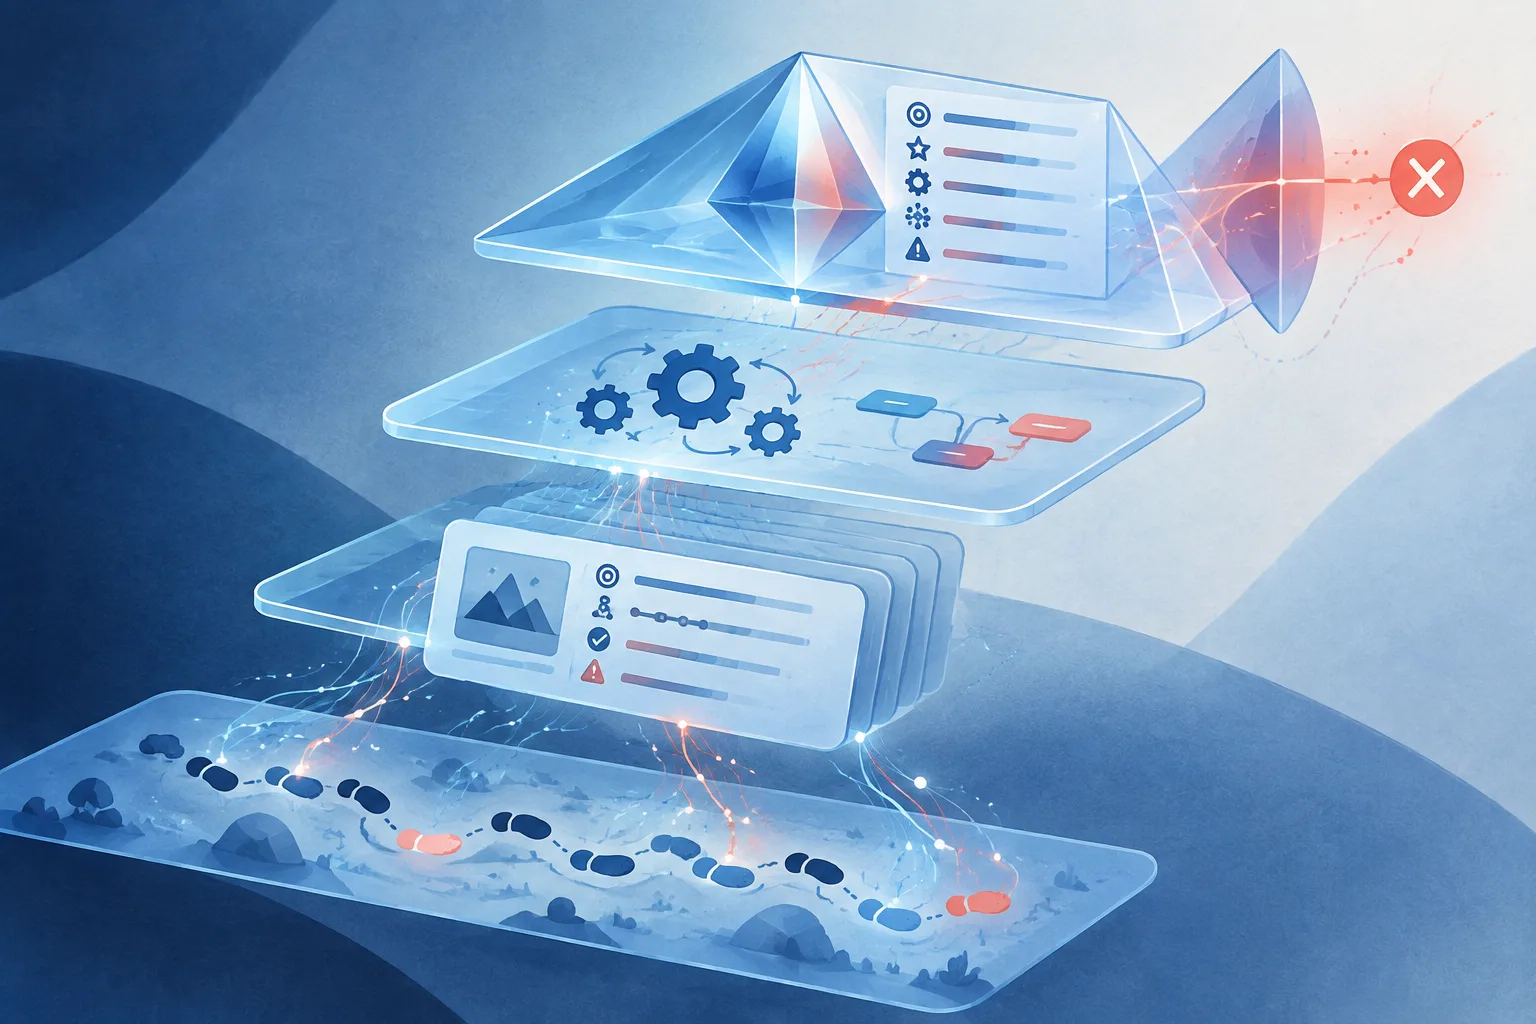
Retrieval is only the first half of the design. For a new task, the agent produces a short plan and uses that plan with the task description to retrieve relevant material from the hierarchy. SAGA then instantiates any retrieved principle into one operational constraint for the current situation, or suppresses it as not applicable. The paper explicitly gives task instructions precedence over memory, treating retrieved knowledge as conditional guidance rather than a script that must be copied.
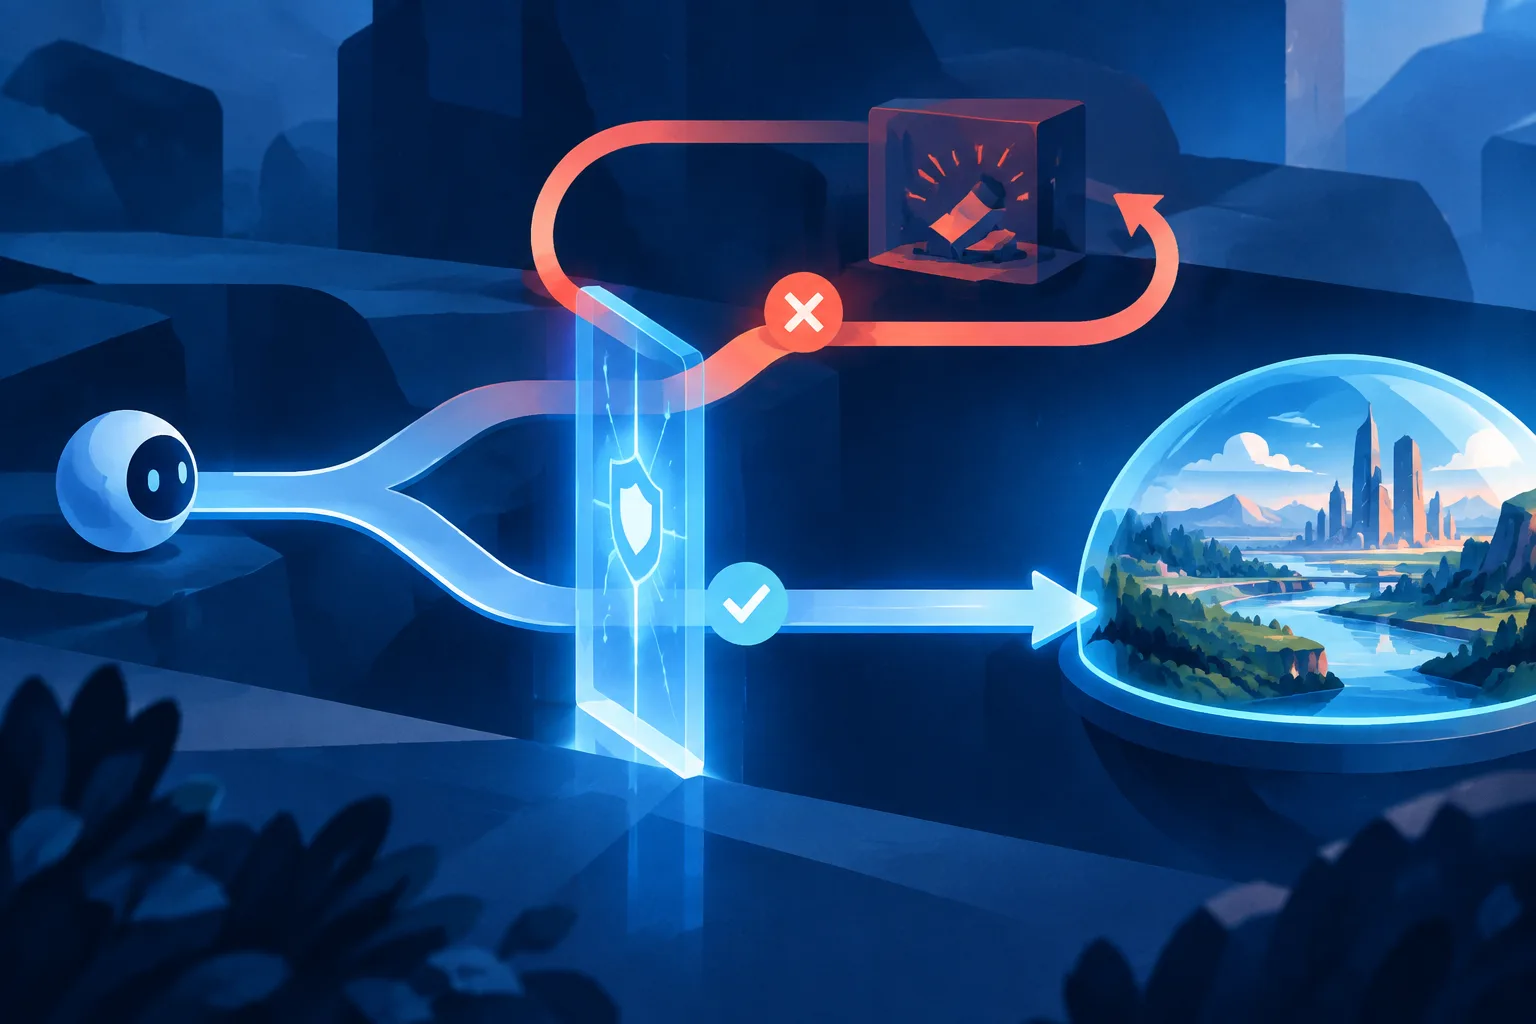
The second half is action regulation. Principles judged harmful when violated can be compiled into executable predicates that inspect a proposed action. If a check fails, the violated principle is returned as corrective feedback and the agent resamples, with a limit of three attempts. If none of those alternatives passes, the framework executes the original action. The authors stress that successful compilation does not prove a predicate is valid, so they separately audit its direction, trigger rate and risk of penalizing a good move.
On ScienceWorld, the paper reports gains for two prompt-based backbones under a strict 175-item evaluation. With DeepSeek-flash, the complete hierarchy scored 56.2 on average, compared with 25.0 without memory and 54.8 using direct trajectory retrieval. With Qwen3.8-Max, the corresponding scores were 67.0, 48.4 and 63.7. That comparison suggests most of the improvement over no memory came from retaining experience at all, while the extra abstraction layer added smaller gains over retrieving trajectories directly.
A separate paired ScienceWorld analysis produced a sharper warning about how abstract knowledge is used. Directly injecting the same principle-level knowledge had a negative estimated effect of 0.0155 on the study’s zero-to-one score scale, while first adapting that knowledge to the current task produced a positive effect of 0.0365. The isolated contrast attributed 0.0520 to instantiation. The authors caution that this analysis used a different harness from the main strict evaluation, and more than 80 percent of its episodes ended with zero score.
Results on ALFWorld also expose the limits of a simple success-rate story. With the stronger Qwen3.8-Max actor, SAGA moved from 96.3 percent at the initial round to 99.3 percent after three rounds, a gain of four solved games among 134. A fixed Qwen2.5-7B actor paired with the complete hierarchy rose from 45.5 percent to 59.4 percent. But no top-level principle in that fixed-model configuration passed validation during the reported rounds, so the authors decline to attribute its improvement to validated principles.
The preprint leaves several important questions open. In the training-based pipeline, Qwen3.8-Max built the abstractions while Qwen2.5-7B-Instruct served as the policy being optimized, so the experiment does not isolate how much the stronger builder’s pretrained knowledge contributed. Some remaining ScienceWorld failures were execution problems rather than knowledge gaps, such as finding an object but failing to submit the final answer. Most importantly, the authors describe their extracted principles as evidence-supported hypotheses, not causal laws, and say their generality beyond ScienceWorld and ALFWorld is still unverified. SAGA’s contribution is therefore a testable architecture for disciplined memory use, not proof that an agent has learned universal rules.
Comments
Loading comments…