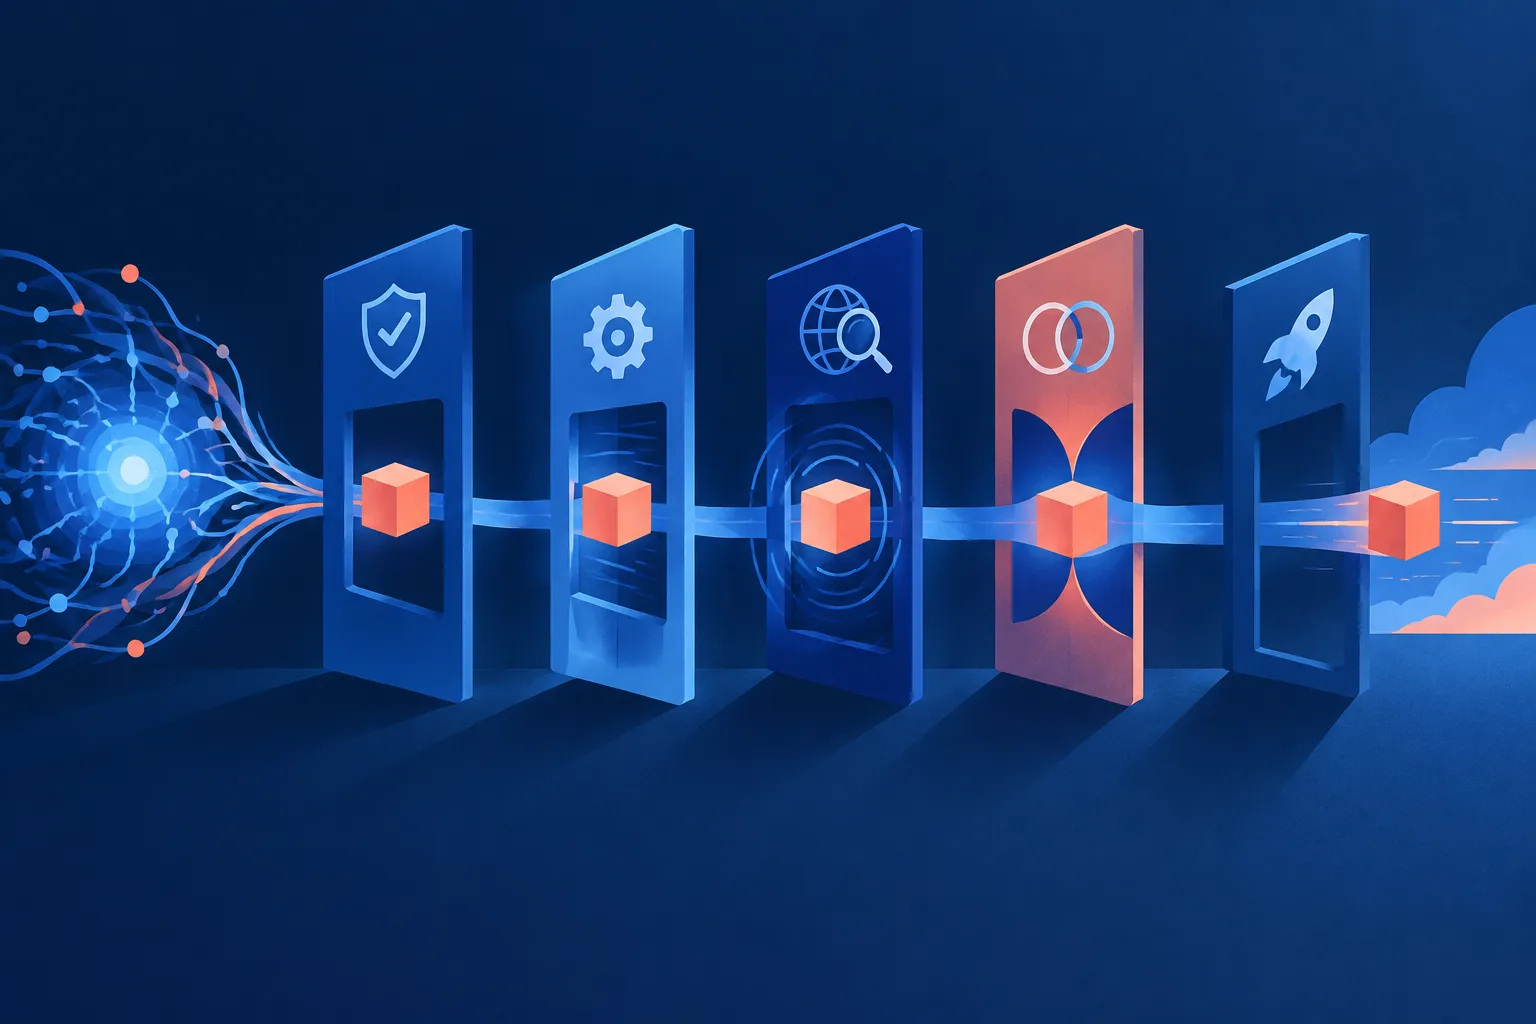
An AI agent can say it acted without proving that the intended result occurred. A new preprint introduces Praxa, an agent harness designed to keep a model’s proposal, permission to act, dispatch, verified external effect, and promotion into service as separate claims rather than collapsing them into one apparent success.
Independent researcher Stefan G. Creadore describes an authority-to-effect chain in which a model or client proposes an action, deterministic policy decides whether it is allowed, a broker executes it, external evidence verifies the result, and review controls whether a change is promoted. The system also includes reconciliation for cases where an outcome remains uncertain.
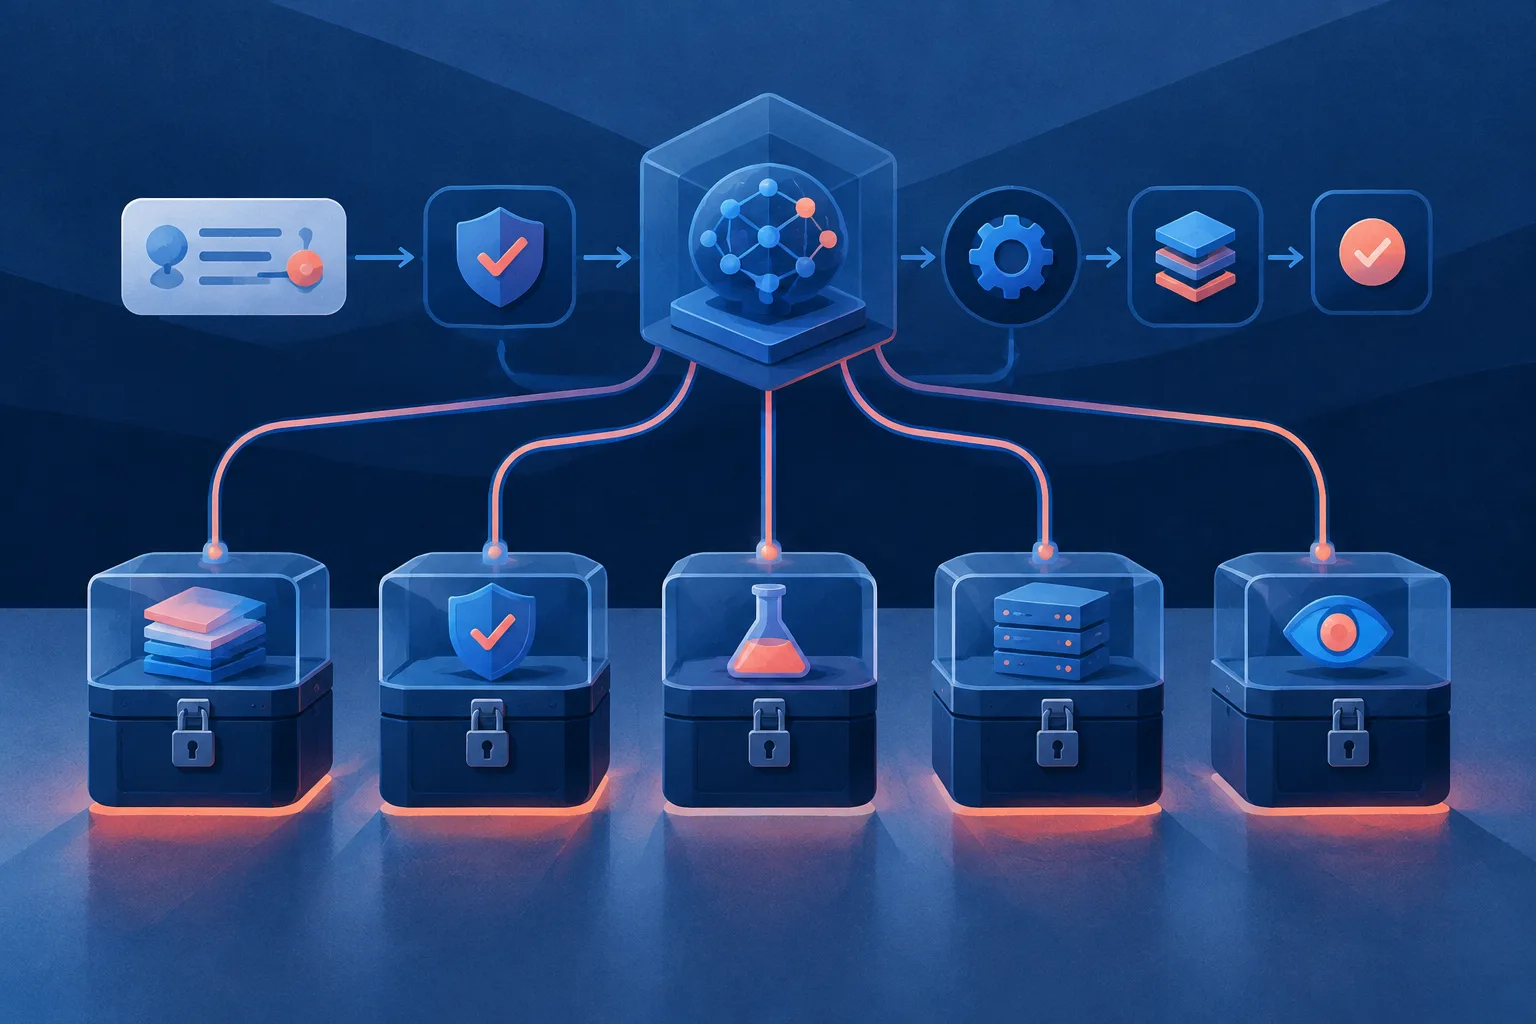
That separation matters because a tool call can be accepted without producing the expected external state. The paper argues that source-code checks, runtime validation, provider-backed experiments, deployment records, and production observations answer different questions. Under this framework, a passing test cannot prove real-world benefit, and a deployment receipt cannot establish model quality.
The paper reports a repository-local audit at a pinned revision that passed 1,027 unit tests and 89 Workerd tests while instrumenting all 363 expected source files and meeting four coverage floors. Those results were generated by the author, however, and the paper says raw per-test transcripts and an independent reproduction were not available. The evidence therefore supports bounded implementation claims, not a security proof.
A separate Terminal-Bench Core pilot compared a baseline agent loop with a reliability-oriented layer across 12 selected tasks and 36 strict trials per arm. Each arm passed 17 trials. The reliability layer consumed 37.49 percent more input tokens and 50.73 percent more output tokens, so the authors explicitly say the pilot does not show that it is superior.
In a post-debug development comparison using a coordination proxy, both the baseline and a source-authored candidate completed 180 of 180 trials with the same measured accuracy, full hermetic crash recovery, and no protected violations. The candidate used fewer tokens, lower estimated endpoint cost, and fewer steps, but the paper cautions that this does not demonstrate better quality, latency, or production behavior.
Praxa’s supported contribution is therefore architectural: it makes transitions from authority to verified effect visible and testable. The current evidence does not establish adversarial security, production safety, general superiority, autonomous recursive improvement, or user benefit. That restraint is central to the paper’s message—agent systems need evidence attached to each claim, especially when model outputs can trigger consequential actions.
Comments
Loading comments…