A research team from the University of Texas at Austin and Amazon has proposed a different way for AI agents to recover when a long sequence of actions goes wrong: preserve the parts of the plan that still work and regenerate only the damaged region. In a preprint submitted to arXiv on October 7, the authors describe Plan-and-Patch, a framework that uses a diffusion language model to generate structured plans and fill in selected sections after execution failures. The results are promising, but they come from controlled benchmarks and should not be treated as proof that the approach will transfer unchanged to deployed agents.
Long-horizon agents often depend on plans that connect subgoals, tool calls and expected observations. A tool may return an unexpected result, an action may fail or an assumption about the environment may turn out to be wrong. Many planning systems respond by rewriting a large portion of the plan. Plan-and-Patch instead represents a plan as an ordered hierarchy of addressable subgoals and steps, allowing a failure detector to identify a region for revision while leaving the surrounding text fixed.
The repair operation matches a native strength of masked diffusion language models. Rather than producing every token strictly from left to right, the model begins with masked positions and resolves multiple tokens in parallel while conditioning on context around them. In the proposed system, the planner receives the failed plan, the selected repair region and feedback from execution. It then fills the masked span while preserving the plan before and after it. A separate executor translates the plan into actions and also selects a repair region from the execution history when a task fails.
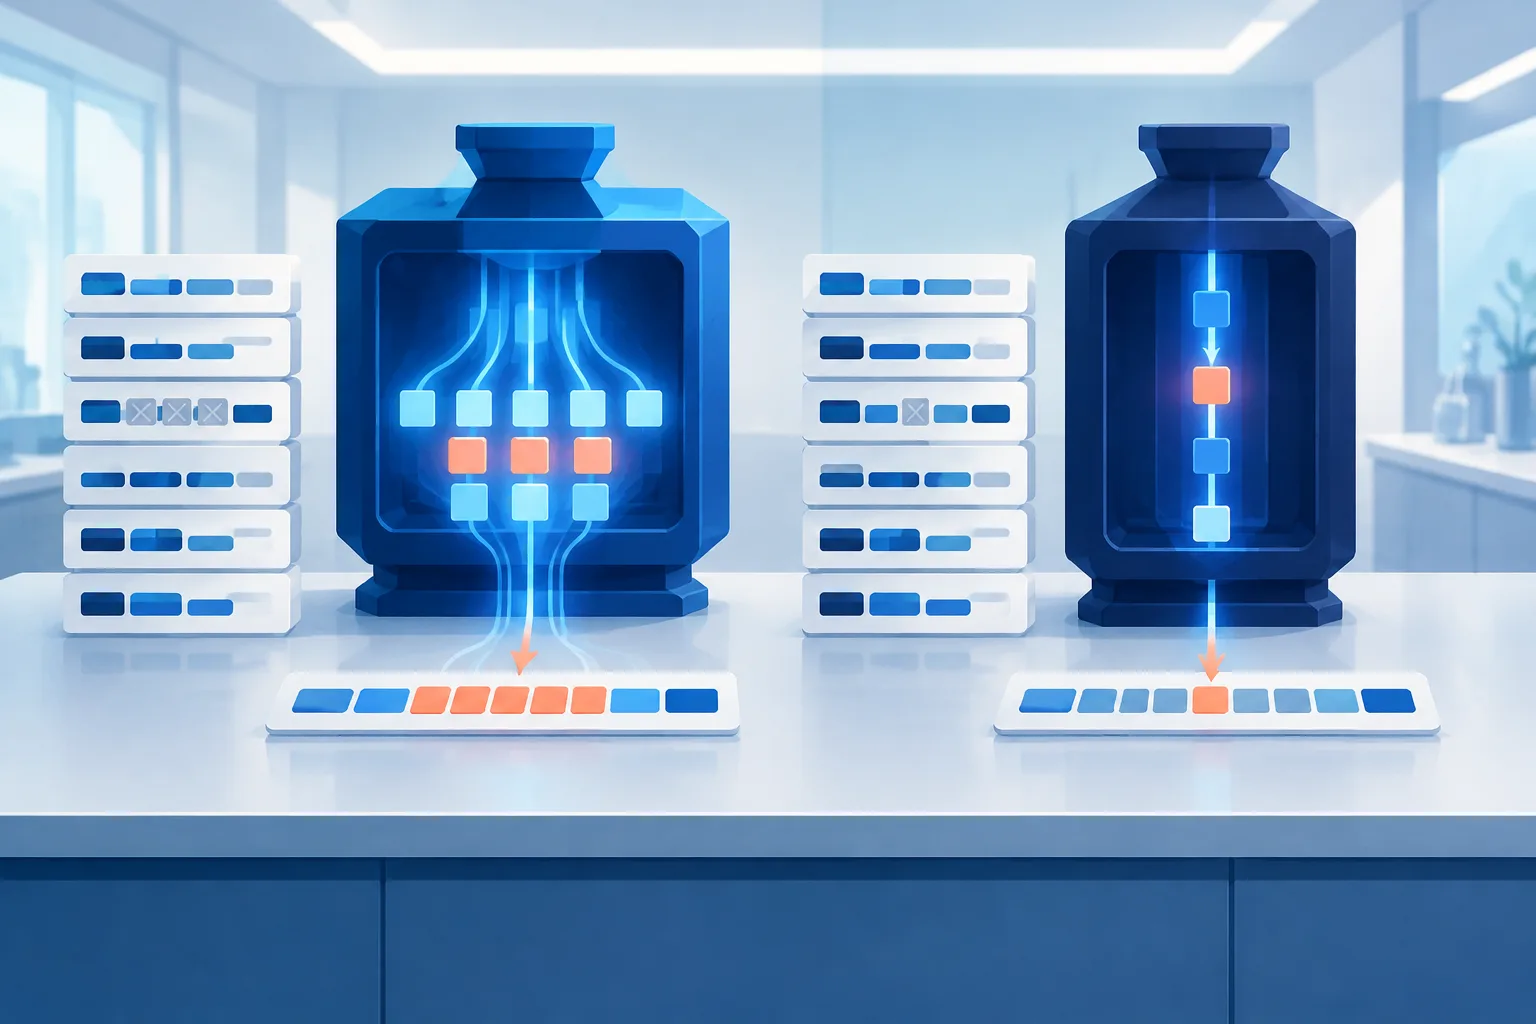
For the principal comparison, the researchers used DreamReasoner-8B as the diffusion planner and Qwen3-8B as the autoregressive planner. Both models had 8 billion parameters, shared a tokenizer, used the same task splits and training examples, and produced the same structured plan format. The models were fully fine-tuned separately for ALFWorld, a household navigation and manipulation benchmark, and TextCraft, a dependency-based crafting benchmark. Their prior training and decoding procedures were not identical, so the comparison is controlled in several important respects but is not a perfect architecture-only test.
The two trained planners produced similar observed generation results, with the autoregressive model holding a small edge. On ALFWorld, plan-generation success was 44.0% for the diffusion planner and 45.5% for the autoregressive planner. On TextCraft, the corresponding results were 63.0% and 66.0%. End-to-end success after history-based repair was also close: 59.9% versus 60.6% on ALFWorld and 68.7% versus 72.2% on TextCraft. Both planning systems outperformed the paper's ReAct baseline on initial generation in those tests.
The clearest reported efficiency gain came from plan generation. The diffusion planner reduced mean generation latency by 39% to 46% across the two environments while achieving similar observed task success. Those measurements used synchronized, unbatched bfloat16 decoding on a single Nvidia A100 and excluded prompt construction, parsing and environment execution. That makes the result evidence of faster model-side planning under the paper's setup, not a guarantee of the same end-to-end speedup in production systems.
A separate Natural Plan evaluation, conducted without task-specific training, showed a sharper tradeoff. Across travel and scheduling tasks, the benchmark validator accepted 53.7% of repairs from the diffusion model and 27.0% from the autoregressive model. Generation went the other way: the autoregressive planner reached 48.6%, compared with 33.0% for diffusion. The authors report that diffusion's repair advantage was concentrated in trip planning, where the structure of flight connections may particularly benefit flexible decoding.
The paper also identifies a practical bottleneck that sits outside the replacement model itself: deciding what to patch. When the system selected regions from execution history instead of receiving reference-assisted selections, pooled repair success fell by 12 percentage points for diffusion and 8.6 points for the autoregressive model. Plan formatting mattered too. Prose-style plans improved generation in additional tests, but the explicitly delimited representation generally supported stronger diffusion repair, suggesting that boundaries useful for editing may not be the same format that best supports initial planning.
Plan-and-Patch therefore offers a concrete design for agents that edit plans locally instead of starting over, and its latency results strengthen the case for diffusion language models as more than an alternative text-generation mechanism. The authors say future work should jointly learn repair-region selection and infilling, adapt the repair scope to uncertainty and test longer planning horizons. Until those pieces improve and the results are replicated beyond these benchmarks, the strongest conclusion is narrower: structured plans can provide a workable interface for parallel generation and localized repair, but finding the correct place to intervene remains a central challenge.
Comments
Loading comments…