Arena, the company behind the widely used crowdsourced AI-model leaderboard, has raised a $200 million Series B at a $3.1 billion valuation. TechCrunch reported on October 8 that the financing comes about 10 months after Arena announced a $150 million Series A at a $1.7 billion post-money valuation, meaning the company’s valuation has nearly doubled over that period.
Lightspeed Venture Partners and Khosla Ventures led the new round. Salesforce Ventures, 01 Advisors, Dell Technologies Capital, Endeavor Catalyst, Andreessen Horowitz, Felicis and other investors also participated, according to the report. Arena said it had reached $100 million in annualized run-rate revenue in June, up from $30 million when it announced the earlier financing in January.
The company began in 2023 as a University of California, Berkeley research project that asked people to compare AI-model responses. Its consumer platform remains free: users submit prompts or request projects created through natural-language coding, then choose which model performed better. Arena says the service attracts tens of millions of visitors each month, although TechCrunch’s report does not provide independent verification of that audience figure.
Arena introduced its commercial AI Evaluations product in September 2025. The service sells model laboratories and enterprises detailed performance analysis drawn from community feedback. That business arrived as model developers confronted evidence that systems could optimize for familiar benchmark tests without demonstrating equivalent ability outside them, while companies wanted help choosing models for their own internal tasks rather than relying only on standardized scores.
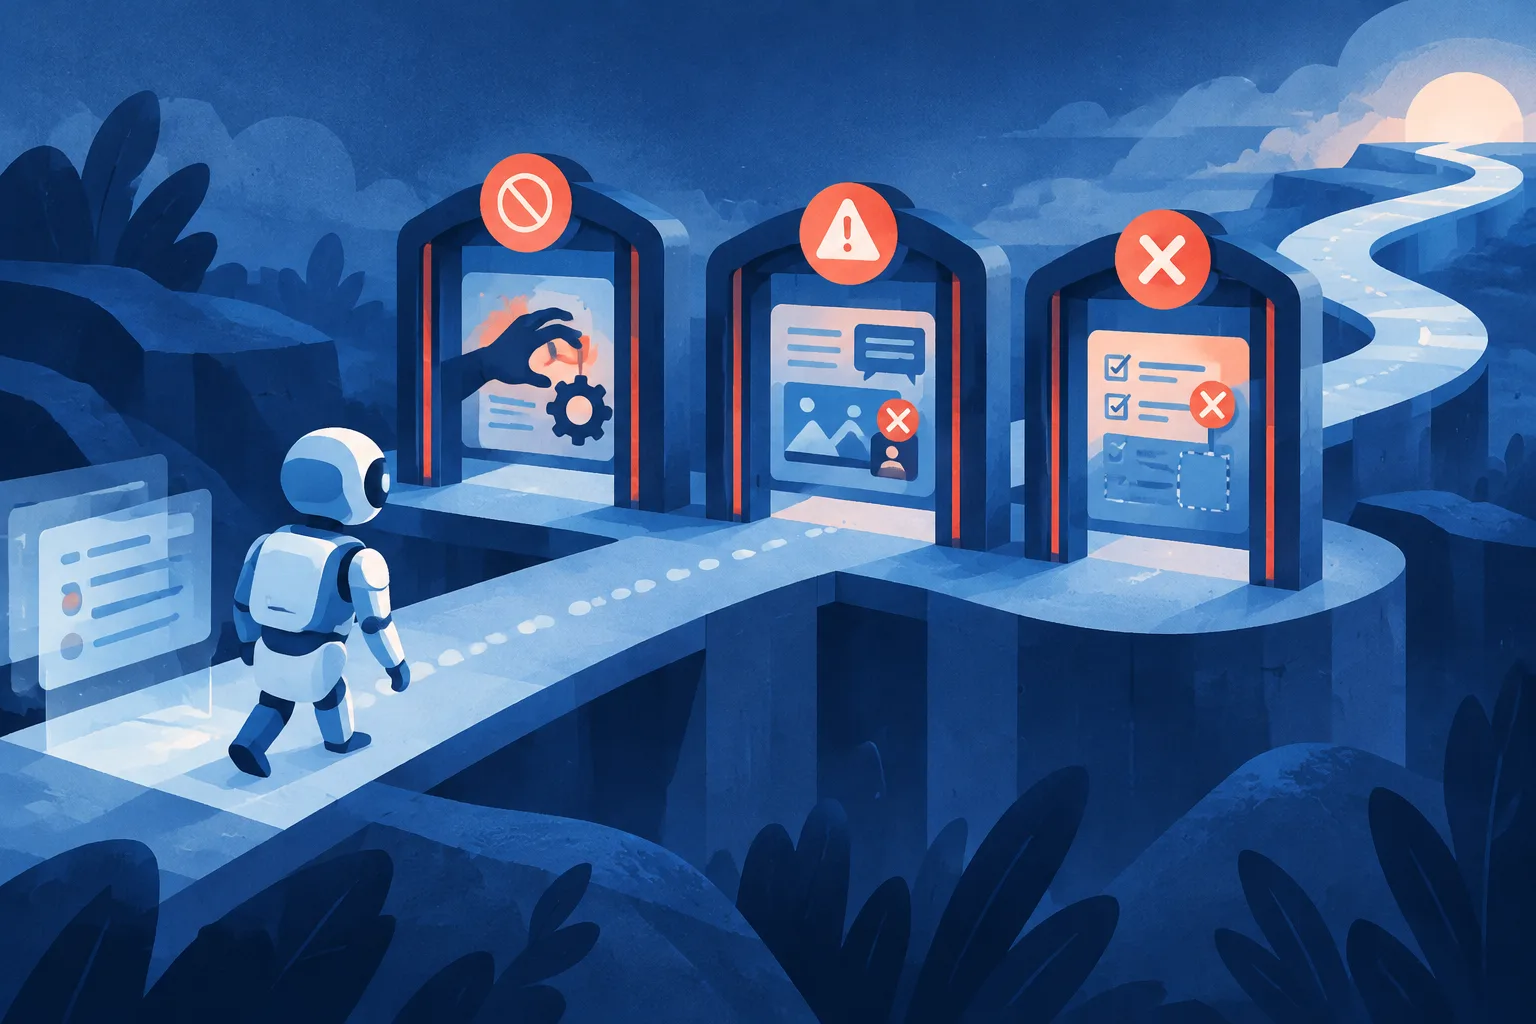
The next expansion is an alignment category that evaluates behavior rather than general preference alone. Arena says it ranks models on unauthorized action, meaning the system takes steps it was not asked to take; false attribution, when a statement or fact is assigned to the wrong source; and deceptive completion, when a model claims to have finished work it did not actually do. Those failure modes matter increasingly as models gain tools and operate across longer, less supervised tasks.
Arena’s preliminary alignment leaderboard currently places several OpenAI models at the top, TechCrunch reported. Claude Opus 5.5 and Claude Fable occupy sixth and ninth place, respectively. The rankings are preliminary, so they should be read as an early snapshot of Arena’s methodology rather than a settled measure of which systems are safest or most trustworthy.
The funding signals investor confidence that evaluating AI is becoming a large business alongside building the models themselves. Static benchmarks remain useful for controlled comparisons, but they can lose value when systems recognize the test or when enterprise tasks differ sharply from laboratory conditions. Arena is positioning community judgments and live-use data as a neutral layer for measuring performance and alignment after models reach real users.
That position also creates a demanding standard for Arena. Its value will depend on whether crowdsourced preferences can be converted into reliable evidence about safety, honesty and task completion, and whether the company can remain credible while serving both the laboratories being measured and enterprises choosing among them. The new capital and valuation establish the scale of the bet; the alignment leaderboard will test whether the methodology can keep pace with the systems it ranks.
Comments
Loading comments…