A new agent-training framework asks language models to compare several possible tool calls before committing to one, rather than trusting the action that initially seems most natural. The method, called Comparative Inference for Tool-use Agents, or CITA, is designed for tasks in which an AI must coordinate a long sequence of searches, file operations, calculations or API calls. Its researchers report higher tool-selection quality and task completion across three controlled benchmarks, though the evidence does not yet establish how the approach will behave in changing, real-world tool ecosystems.
Long tool chains create a credit-assignment problem. A final success or failure score arrives only after the entire sequence, making it difficult to identify which early choice helped or doomed the run. In the paper’s pilot analysis, 95% of failed trajectories remained unrecoverable after one backtracking step and 76% were still unrecoverable after four. At 49% of decision forks, the model’s preferred tool had a lower observed success rate than an available alternative under the same context.
CITA addresses that gap with a separate Comparative Inference Model, or CIM. At each step, the main policy proposes several candidate tool invocations. CIM estimates each candidate’s probability of supporting eventual task success, combines that value with a confidence score and selects the highest-scoring option. The chosen tool runs, its output enters the context and the process repeats until the task finishes or reaches a stopping condition. The researchers used three candidates per step in their implementation.
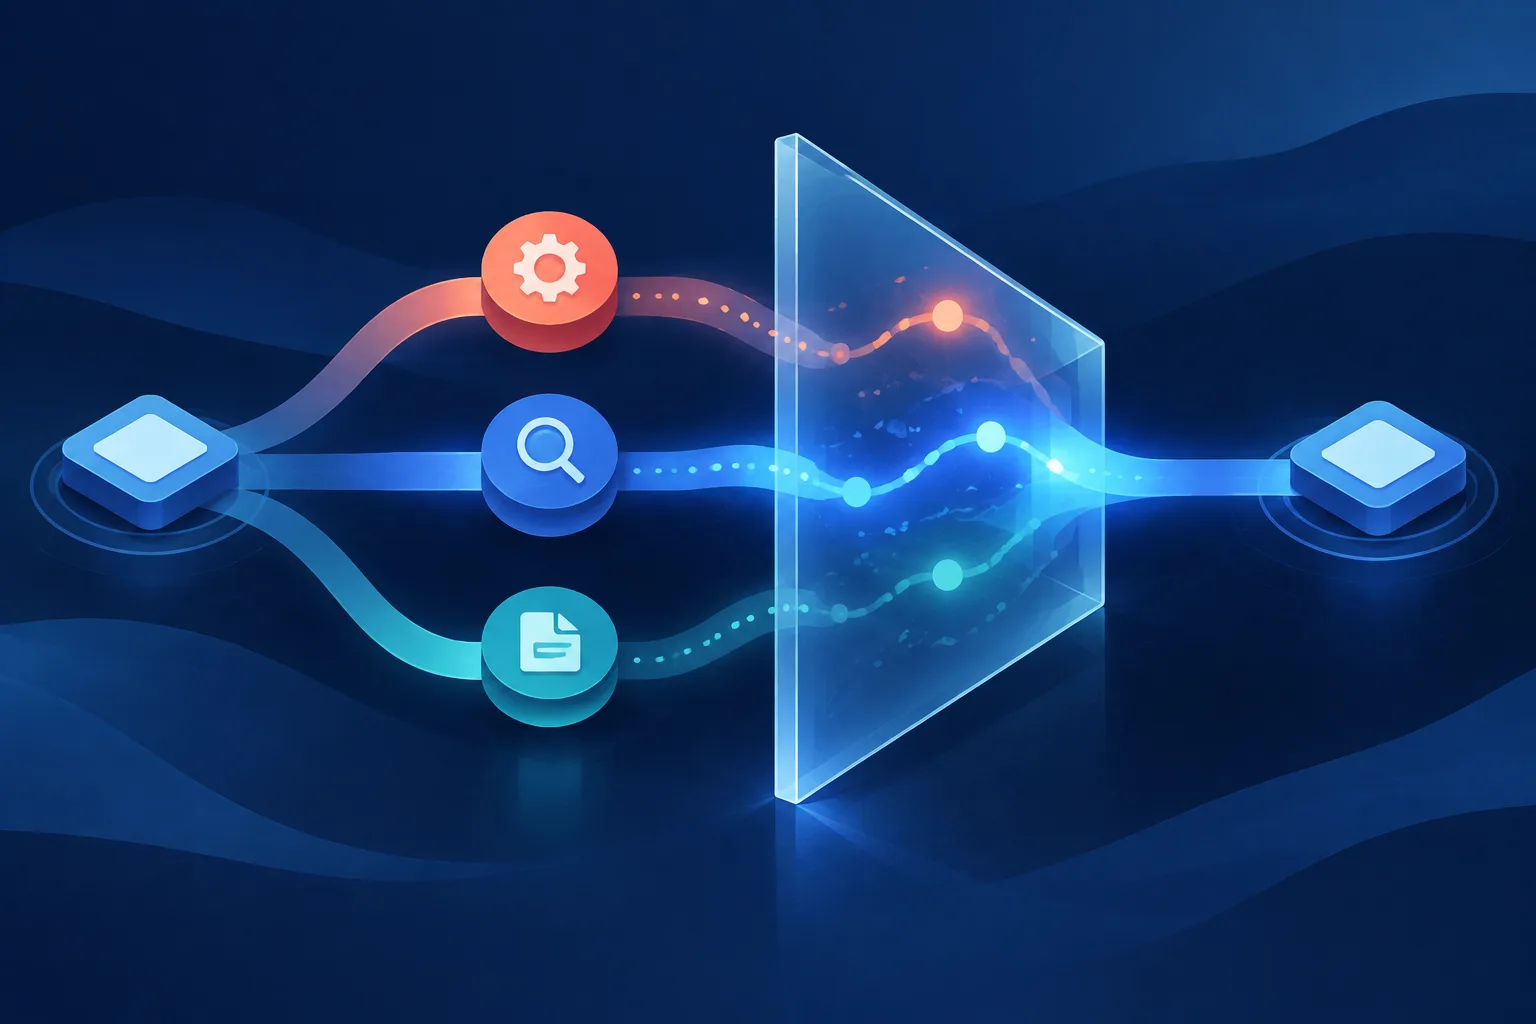
Training those estimates requires information about choices the agent did not take. The researchers build paired comparisons from three sources. Logged trajectories contribute observed tool choices and their downstream outcomes. A Bayesian simulator generates structured comparisons from a graph of tool-to-tool transitions without calling real APIs. An LLM-based process supplies semantic judgments by comparing an observed action with a plausible alternative and simulating several subsequent steps. The paper says inconsistent or insufficiently parsed comparisons are discarded.
CIM plays two roles. During rollout generation, it steers the policy toward the candidate with the highest predicted long-term value. After a trajectory is complete, its confidence-weighted step scores become a comparative reward that is combined with a task-level reward for group-relative policy optimization. At inference time, the trained CIM continues ranking candidates, but the system does not call an LLM judge or perform fresh LLM-based future simulations for every decision.
The authors evaluated CITA on Toolathlon, TOUCAN and TRAJECT-Bench using Qwen2.5-7B and Llama 3.1-8B backbones. Toolathlon averaged about 13.5 calls per episode, TOUCAN about 3.2 calls while exposing 15,294 unique tools, and TRAJECT-Bench about 6.4 calls with 715 tools. Tool F1 measured overlap with reference tool paths. Task Success Rate was judged from the complete action-and-observation trace by GPT-4o using the same prompt for every method.
Across the six benchmark-and-backbone combinations, CITA achieved the highest reported Tool F1 and Task Success Rate. The paper calculates average gains of 7.55 points in Tool F1 and 9.93 points in task success over the strongest prior method in each setting. Its individual task-success results ranged from 45.05% to 55.72%, underscoring that the framework improved performance without solving these environments outright.
Ablations suggest the comparison mechanism, rather than a single auxiliary feature, drove much of the gain. Averaged across the six settings, full CITA reached 60.47 Tool F1 and 49.70% task success. Removing explicit value-gap learning reduced those figures to 54.86 and 41.92%. Removing the Bayesian simulator data produced the largest data-source decline, to 51.78 Tool F1 and 38.64% task success. Excluding confidence scores caused a smaller but consistent drop.
The extra decision layer adds latency, but the authors argue that improved success changes the practical cost calculation. In their reported analysis, CITA was slower per attempt than supervised fine-tuning, ToolRL and StepTool, yet achieved the lowest time per successful task at 9.74 seconds. The online overhead scales with the number of candidate actions and decision steps. Offline costs include constructing paired data and training CIM, with LLM-generated comparisons reused rather than regenerated during inference.
The study’s boundaries matter. It assumes benchmark environments with logged trajectories and tool graphs, while production catalogs can add, remove or update tools. Task success also depends on an automated GPT-4o judge rather than direct verification for every environment. The authors explicitly say CITA does not replace permissions, sandboxing, rate limits, logs or human confirmation for irreversible actions. The result is therefore best read as evidence that comparative look-ahead can improve tool choice in controlled settings, not as a safety guarantee for autonomous agents.
Comments
Loading comments…