A broad coalition of veterinary, computing, legal and data specialists has proposed VETNET, a shared system of benchmark datasets and evaluation tools for artificial intelligence in animal health. The plan, described in a 32-page white paper submitted to arXiv, is still a roadmap rather than a finished platform. Its immediate objective is deliberately narrow: produce one usable benchmark package with a defined task, governed data access, documented labels, a runnable evaluation process and a way to revise the work after feedback.
The authors argue that veterinary AI has begun spreading into clinical documentation, imaging, triage, client communication and decision support without the common testing infrastructure available in more mature medical-AI research. Animal health also poses unusually difficult evaluation problems. Records differ across practice-management systems, outcomes can be sparse, terminology is inconsistent, and models may need to work across species, breeds, equipment, regions and clinical settings. A benchmark built for human care cannot simply be imported into that environment, the paper says.
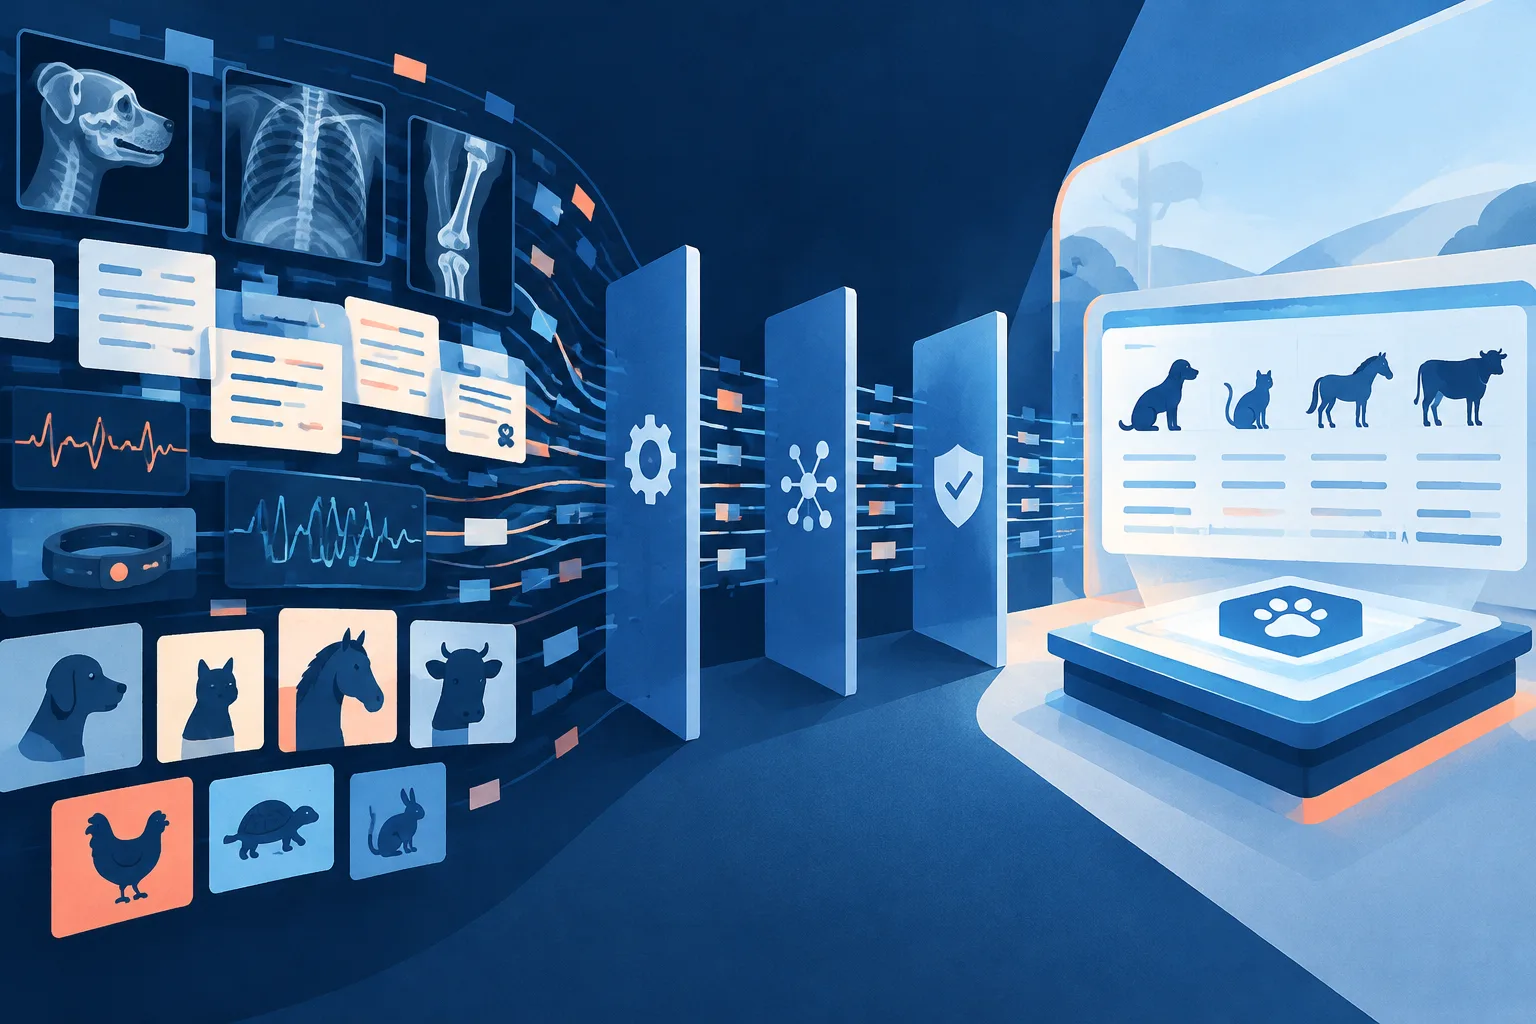
VETNET's proposed answer is not a single public data dump. It is an ecosystem combining curated datasets, metadata standards, task definitions, protected test sets, evaluation metrics, documentation and responsible-use rules. The repository would support multiple access tiers: relatively low-risk material, such as deidentified imaging or animal-only sensor streams, could be suitable for early pilots, while records containing farm identity, financial details, rare cases or proprietary vendor data could require controlled, federated or local evaluation. The authors summarize the philosophy as open where safe, controlled where necessary, and federated or hybrid where practical.
That structure reflects a central warning in the paper: a high benchmark score is not proof that a model is ready for clinical use. The proposed evaluations would include private holdout sets, external-site and time-based testing, and subgroup results broken out by factors such as species, breed, geography, device and practice type when the data permit. Evaluators would also look for shortcuts, including scanner signatures, local text templates or information recorded only after an outcome. For higher-risk tasks, the paper calls for reporting calibration, uncertainty and when a model abstains.
The plan treats labels as designed artifacts rather than unquestioned truth. Veterinary records may lack post-mortem confirmation or another diagnostic gold standard, so every dataset would need to explain who created its labels, under which protocol, and which errors matter clinically, economically, ethically or for animal welfare. VETNET would also distinguish technical benchmark testing from external and temporal validation, and from the later veterinary studies required to support real-world deployment claims.
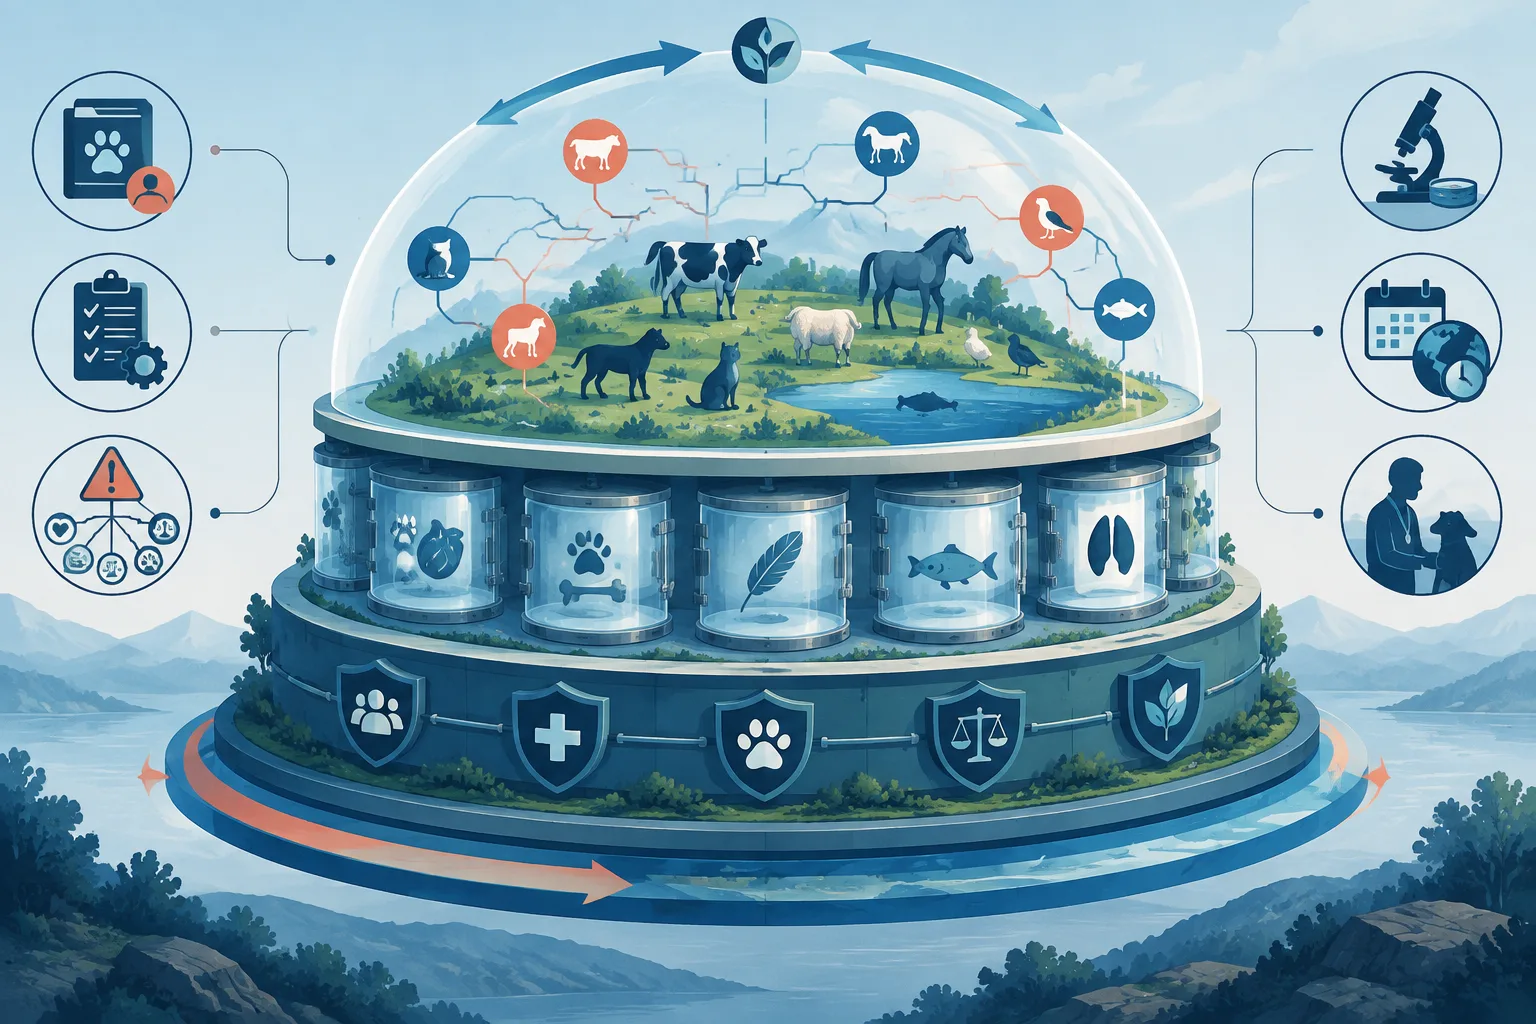
Governance is presented as part of the technical system, not paperwork added at the end. The white paper raises questions about revoking access after misuse, correcting or withdrawing contributed data, handling old scores after a benchmark changes, detecting leakage from protected test sets, and limiting commercial claims. It also notes that animal records can expose client information, farm operations and business-sensitive data even though veterinary medicine lacks a direct equivalent to the U.S. health-privacy law that governs human medical records.
The first-year roadmap calls for one complete benchmark loop before the initiative tries to cover its stated long-term ambition of any animal, any disease and any responsible task. Candidate pilots include canine or feline radiography, companion-animal oncology and livestock disease surveillance. During the first three months, organizers would identify data contributors and a pilot; by months three to six, they would draft access rules and annotation protocols and deploy an early prototype; later stages would add an evaluation harness, baseline workflow and a controlled pilot release.
The proposal grew from a Cornell-hosted summit held in June 2026 with 36 participants from six countries and 16 institutions. That breadth gives the project access to expertise that no single veterinary hospital or AI lab is likely to contain, but the paper is explicit about what remains unresolved: funding, institutional partnerships, governance authority, data rights, maintenance and evidence that the first benchmark works. VETNET's significance therefore lies less in a product launch than in its attempt to define the tests veterinary AI should have to pass before performance claims reach clinicians, owners, producers and the animals affected by those decisions.
Comments
Loading comments…