Apple has developed an internal distributed system that combines idle graphics-processing capacity across networked Macs for machine-learning inference. The Register reported on October 13 that the system, called Minions, is already being used inside the company to give teams faster access to compute that would otherwise sit unused.
Apple’s researchers describe Minions as a dynamic virtual GPU cloud built from Apple Silicon machines running macOS. Rather than treating each Mac as an isolated workstation, the system places available devices into a shared pool of inference workers. Jobs can then be divided into subtasks and assigned to machines with spare capacity.
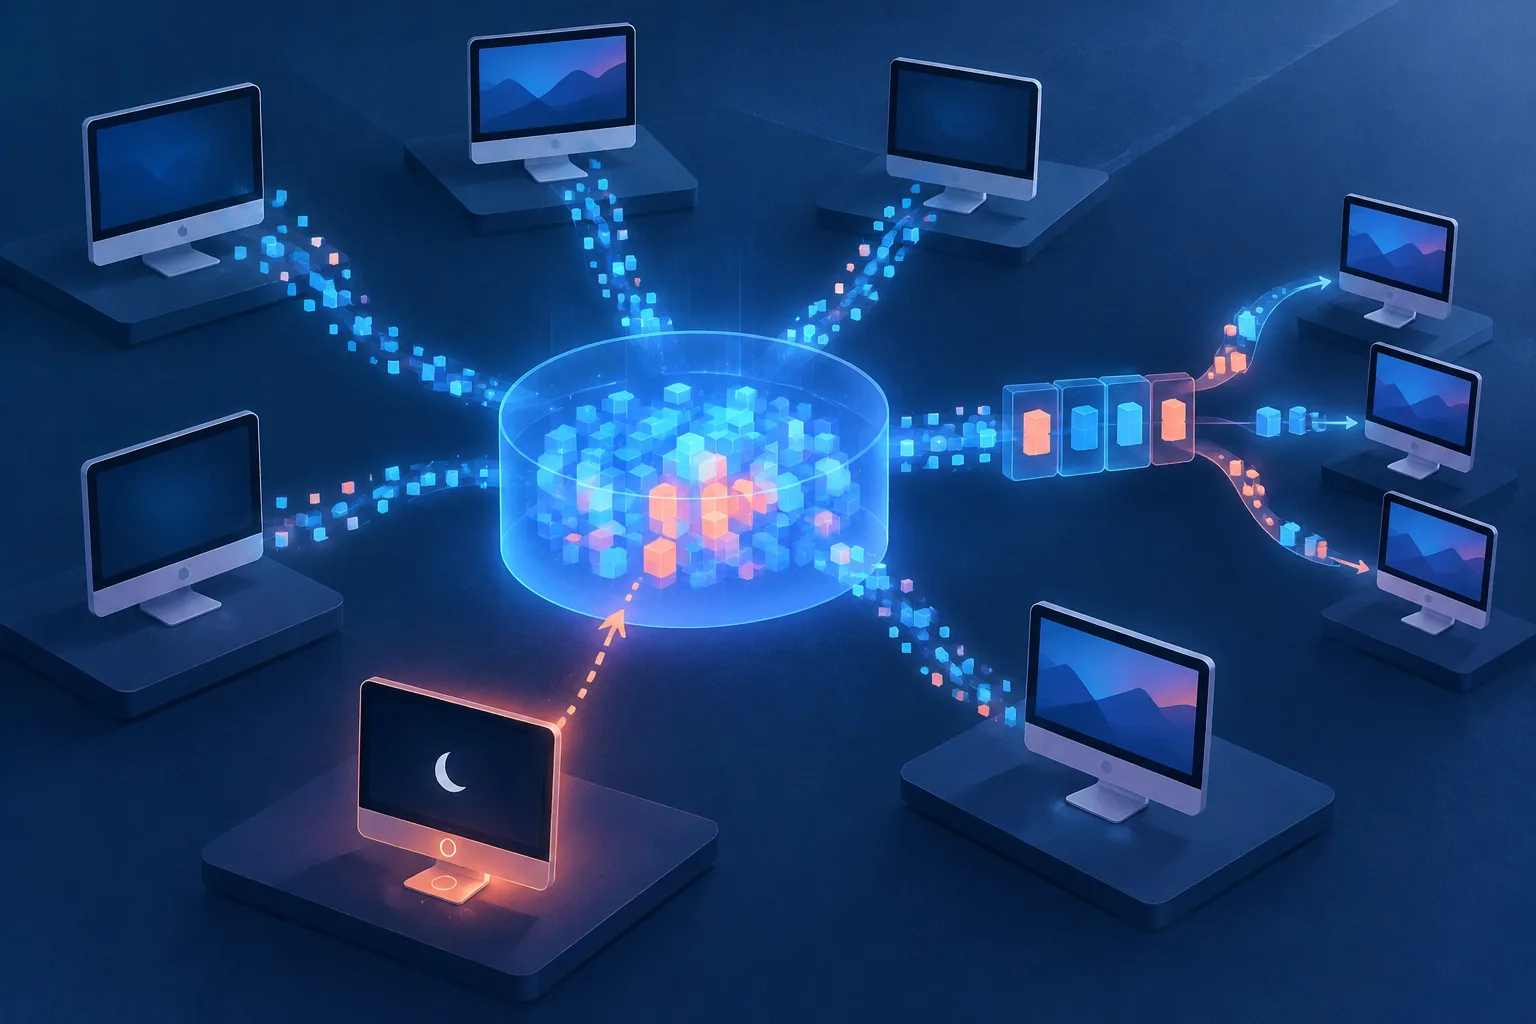
The immediate benefit is shorter access time. According to the paper cited by The Register, some inference jobs previously waited more than ten hours because centralized GPU capacity was limited. With Minions drawing on idle Macs, those tasks can often begin within minutes. The reported improvement concerns queue time rather than a claim that each individual machine becomes faster.
Minions is not simply a cluster for loading one enormous model. Apple’s recently released Mac mini and Mac Studio can combine compute and memory through Remote Direct Memory Access over Thunderbolt 5, which can help accommodate a workload too large for one machine. Minions has a different emphasis: broad hardware availability, fault tolerance, and the redistribution of idle resources across a network.
The architecture has four principal components. A Minion Server coordinates work and makes requested jobs available as subtasks. A PostgreSQL Metadata Store retains task information. A Minion Executor runs an inference subtask on a Mac’s GPU, sends the result to S3, and reports its status to the server. A Minion Watchdog looks for failures, including an unresponsive Mac, and reassigns affected work.
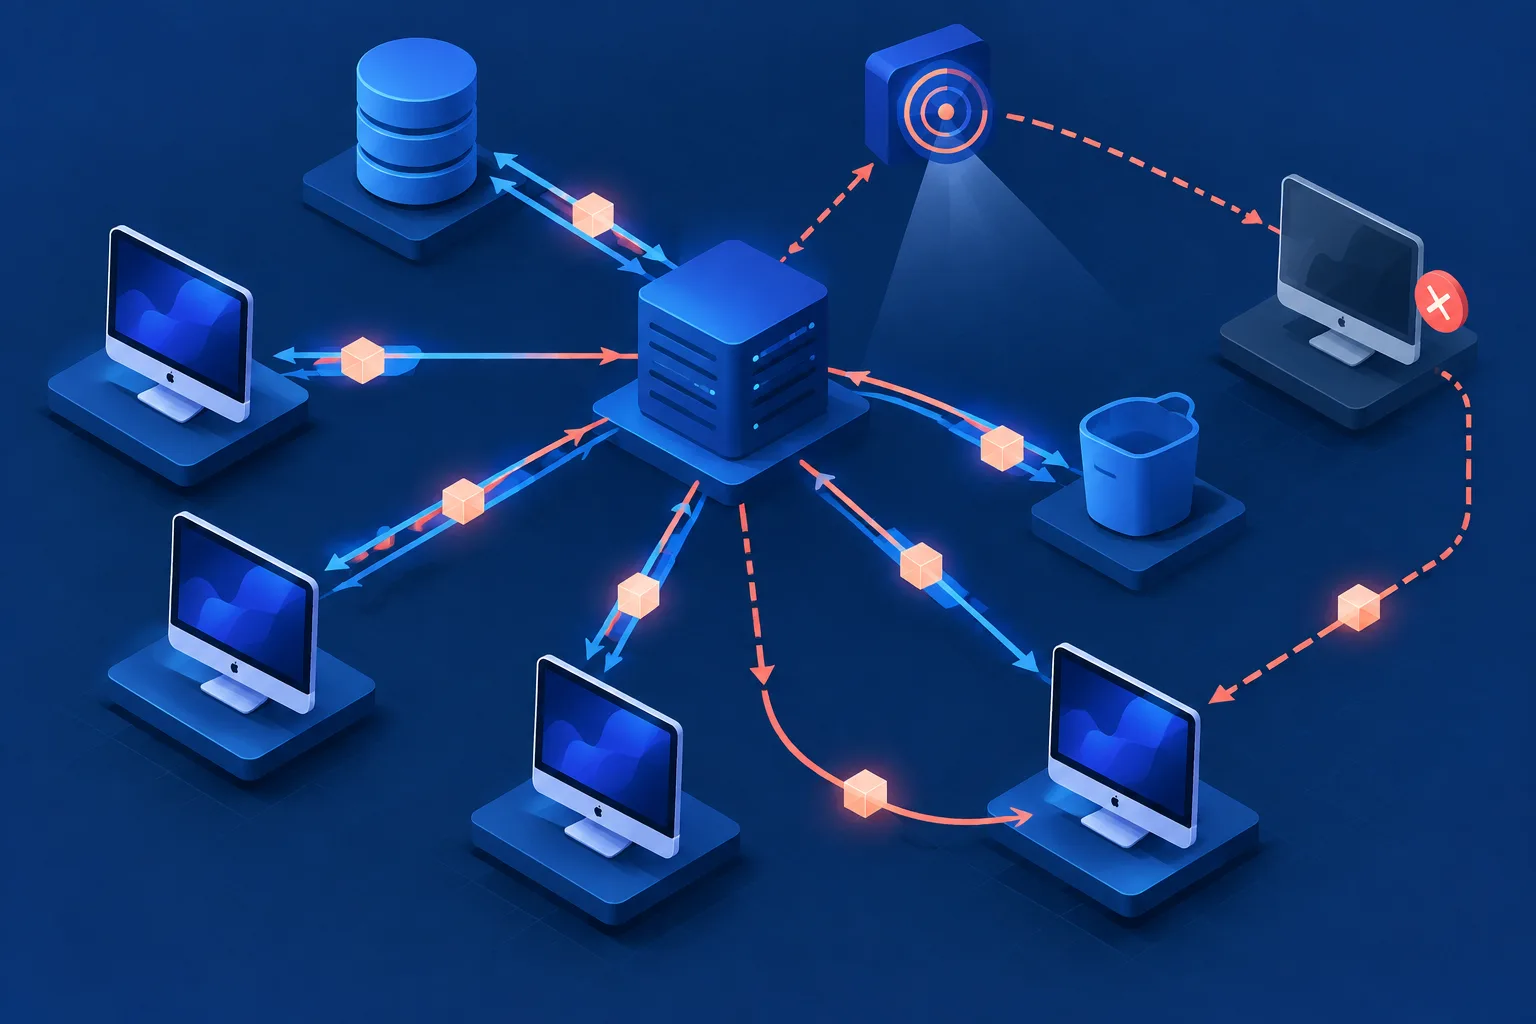
That design treats ordinary corporate hardware as a flexible internal service. If one worker disappears, the watchdog can move its assignment elsewhere instead of allowing the entire job to fail. The system also sends database statistics to Grafana-based dashboards for real-time visibility, according to The Register’s account of Apple’s research.
The comparison with an Nvidia GPU cluster has limits. Conventional purpose-built clusters are optimized around throughput, latency, and efficient use of high-end accelerators for large models. Apple’s system is aimed at making already-deployed Mac hardware easier to find and use. Its value comes from coordinating fragmented capacity, not from claiming that a fleet of office Macs can replace specialized datacenter infrastructure.
Minions illustrates a broader operational shift in AI computing: organizations can look beyond buying more centralized accelerators and ask how much existing hardware remains unused. Apple’s reported results do not establish the cost, scale, or performance of a commercial service, and the system is described as an internal platform. They do show that pooling idle machines can relieve a real inference bottleneck when availability matters more than maximum per-job performance.
Comments
Loading comments…